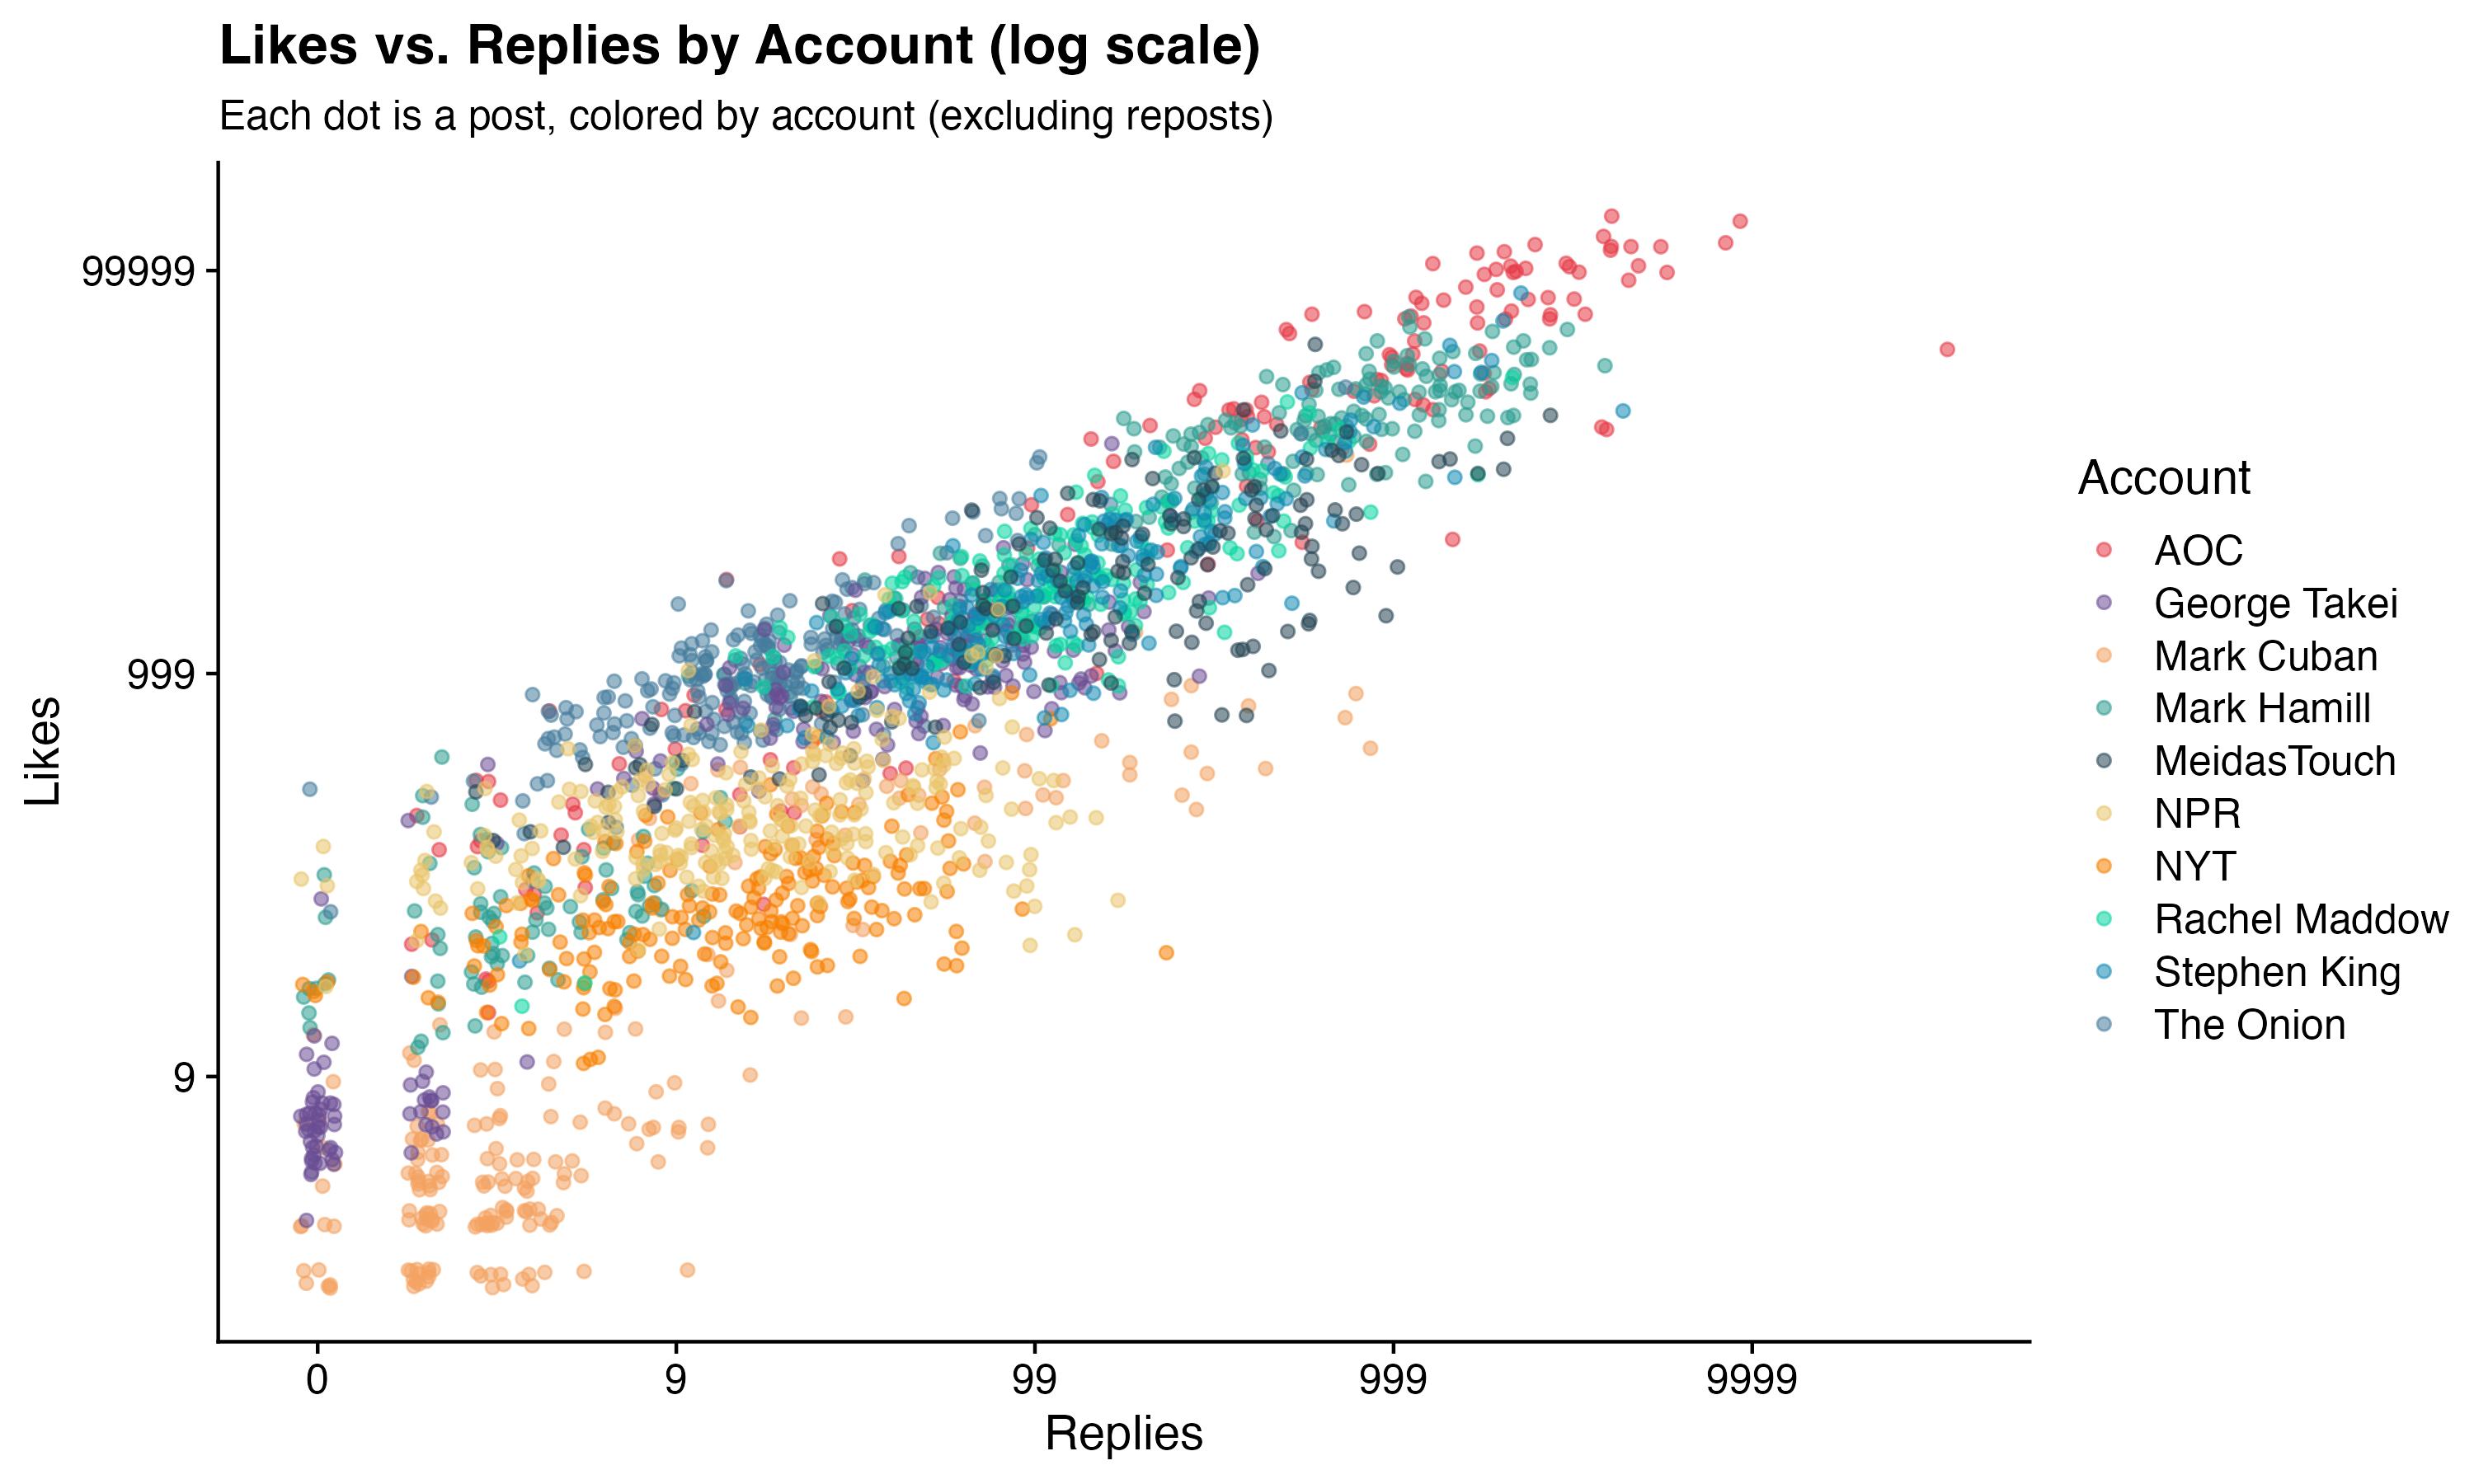The short version: large language models are increasingly used to code open-ended survey responses, but they systematically over-classify, assigning categories too liberally on ambiguous cases and producing high sensitivity with low precision. Survey methodologists have long known that aggregating multiple noisy annotators beats any single annotator, so the talk asked whether the same principle transfers to LLMs. Across four open-ended survey questions with human-coded ground truth (3,208 responses) and 16 models spanning three cost tiers and six providers, unanimous voting across models corrects the problem directly: on the most ambiguous categories, the false positive rate drops from 50% to 3% and precision triples. The benefit concentrates exactly where over-classification is worst, on subjectively ambiguous categories with fuzzy boundaries, and it replicates across three independent datasets.
The part I most wanted a room of survey researchers to hear is what drives the correction. It is decorrelated errors, and the most reliable way to get them is cross-provider diversity: models from different providers err differently on ambiguous cases, and consensus filters out the idiosyncratic false positives. Temperature variation and scaling up within a single model family do not reliably do the same. As few as three diverse lower-tier models are enough to beat GPT-5. If you only take one thing from the talk, it is that investing in a few different models is more effective than investing in one expensive model.
The work is written up in Model Diversity Over Model Size (preprint on SocArXiv, currently revise and resubmit at Public Opinion Quarterly), and unanimous multi-model ensembling ships as a default in CatLLM.
Thank you to the PAPOR organizers and to KFF for hosting. It was a great group to be in conversation with, and I hope to be back.
]]>Contact Informationchrissoria@berkeley.edu100,000 Downloads: What CatLLM Has Built So Far2026-08-04T00:00:00-07:002026-08-04T00:00:00-07:00https://christophersoria.com/posts/2026/08/catllm-100k-downloads
CatLLM has passed 100,000 downloads on PyPI. I started it because I had a column of open-ended survey responses and no good way to code them at scale; I did not expect it to end up anywhere near six figures.
I want to mark the number, but the number is not really the interesting part. Downloads measure adoption, not whether a tool is any good. So this post is about the two things I think actually matter: what the defaults are grounded in, and what people have built with it.
The Defaults Are Empirical Claims, Not Preferences
Most LLM classification tooling ships with defaults chosen because they seemed reasonable. CatLLM’s defaults are the output of benchmarking studies against human-coded ground truth, and every one of them exists because the alternative measurably failed.
The core finding across those studies is that LLMs systematically over-classify. They assign categories too liberally on ambiguous cases, producing high sensitivity and much lower precision, which means default configurations can substantially overstate how common a theme is in your data. That single failure mode is what most of CatLLM’s defaults are designed to correct:
Verbose category definitions with explicit inclusion and exclusion criteria. Vague category labels are where over-classification concentrates.
Unanimous multi-model ensembling. Requiring cross-provider agreement drops the false positive rate on the most ambiguous categories from 50% to 3% and triples precision.
An automatic “Other” escape valve. Models forced to choose among your categories will force-fit responses that belong in none of them.
Advanced prompting strategies off by default. They showed no reliable benefit on these tasks, so they are opt-in rather than assumed.
The package is also peer-reviewed. It went through review at the Journal of Open Source Software, and the empirical validation behind the defaults is written up separately and under review at disciplinary journals. That is a deliberately slower path than shipping a package and writing a README, and I think it is the right one for tooling that produces variables people then run regressions on.
The Papers
Five papers so far, all of which either document CatLLM or exist because of the validation work behind it. All preprints are open access.
Soria C. High Agreement, Different Stories: How LLM Classifiers Reshape Demographic Patterns in Survey Data. SocArXiv. 2026.
Eight LLMs against human annotators on 3,200 responses and over 19,000 coding decisions. Models hit 82–97% per-category agreement while reproducing the full human label set for fewer than 60% of responses, and the gap is not evenly distributed across demographic groups. Revise and resubmit at the Journal of Survey Statistics and Methodology.
The practical upshot of the last two, if you only take one thing from this section: you probably do not need the expensive model. You need a few different ones.
It Stopped Being a Survey Tool
I built CatLLM for open-ended survey responses. That is still the use case I understand best and the one the validation studies target. But the same three-stage pipeline (explore, extract, classify) turns out to be indifferent to where the text came from, and people have taken it well outside survey methodology.
Some of what it is being used for now:
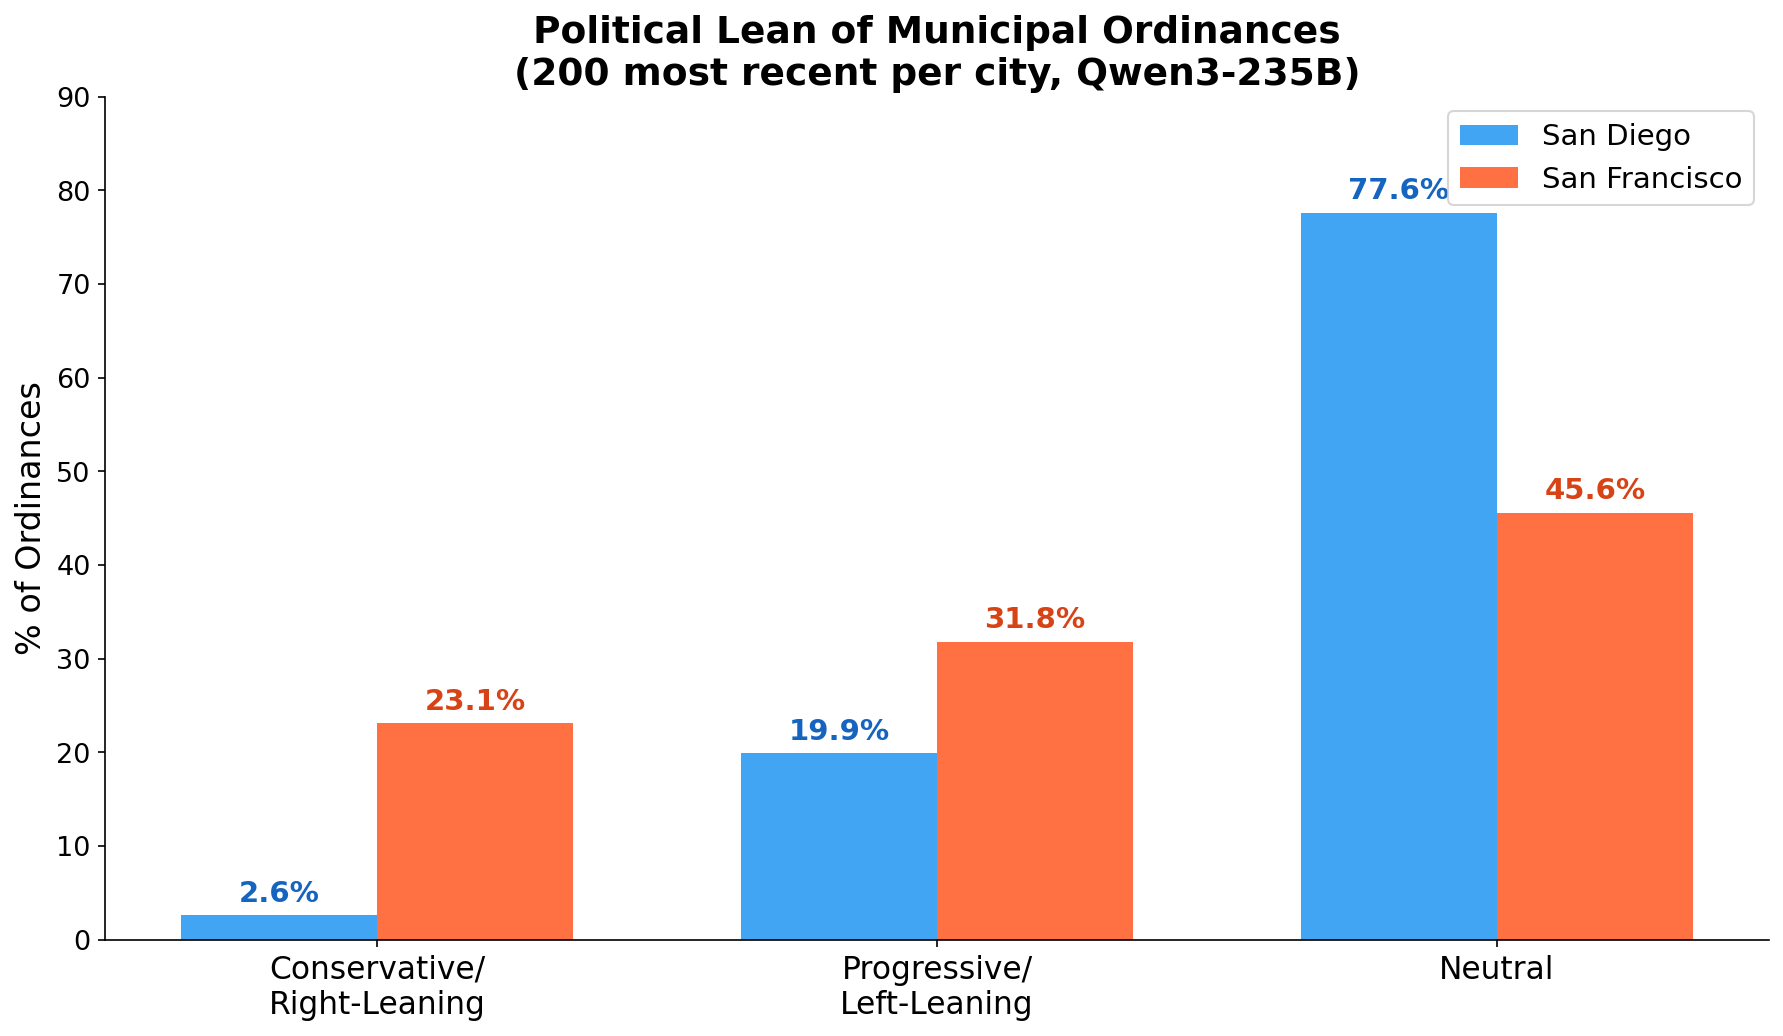
Local policy. Municipal ordinances are dense, high-volume, and almost entirely unanalyzed. I used the pipeline to classify 200 recent ordinances each from San Diego and San Francisco against a policy taxonomy and a political lean scheme; you can read what came out of that.
Social media. People are coding their own posting histories and public platform data. I wrote up analyses of Bluesky and Threads content using the same machinery.
Academic literature. Screening and coding papers at a volume that makes manual abstract review impractical.
Documents and images. PDF and image classification for anything that lives in a scanned archive rather than a clean CSV.
That range is why the ecosystem split into domain packages (cat-pol for political text, cat-vader for social media, cat-ademic for academic writing, cat-web, cat-cog, cat-survey) on a shared cat-stack engine. It is also available in R, in Stata, as a Mac desktop app, as a web app, and through Claude Code for researchers who would rather not write any code at all.
If You’ve Used It, I’d Like to Know
Here is the actual ask.
PyPI tells me the package has been downloaded. It tells me nothing about who, for what, or whether the results held up. I have no way to find the work CatLLM has contributed to unless someone tells me about it.
If you have used CatLLM in a paper, a preprint, a thesis, a dissertation, a class assignment, a report, or a blog post, I would genuinely like to hear about it. I want to maintain a public list of work that used the package, and I want to know which parts held up under conditions I never tested. I am especially interested in:
Non-English text and non-U.S. contexts, which the validation studies barely cover.
Domains I have not benchmarked at all: clinical notes, interview transcripts, historical documents, customer feedback.
Cases where it did not work. Negative results are more useful to me than success stories, and they will shape the defaults for the next version.
Reach me at chrissoria@berkeley.edu, or open a thread on the GitHub repo. No formality needed. A link and a sentence is plenty.
Install It
pip install cat-llm
Everything is open source under GPL-3.0 and it will stay that way. The full pipeline runs on free HuggingFace models or locally through Ollama at zero API cost, and, per the access-tier study, local open-weight models are a real option rather than a consolation prize. There is no paid tier and there is not going to be one.
If you use it in published work, the citation is:
Soria C. CatLLM: A Python package for Generating, Assigning, and Scoring Open-Ended Survey Data and Images. Journal of Open Source Software. 2026. doi:10.21105/joss.09678
Thanks to everyone who filed an issue, reported a bug, or asked for a provider I had not added yet. A hundred thousand downloads is a nice round number, but the issues are what actually made the package better.
]]>Contact Informationchrissoria@berkeley.eduPresenting CADAS at AAIC 2026 in London2026-08-03T00:00:00-07:002026-08-03T00:00:00-07:00https://christophersoria.com/posts/2026/08/aaic-2026-london
On July 12 I presented at the Gateway/HCAP consensus session at the Alzheimer’s Association International Conference (AAIC) in London, sharing work from the Caribbean American Dementia and Aging Study (CADAS) on a multinational framework for online cognitive impairment diagnosis.
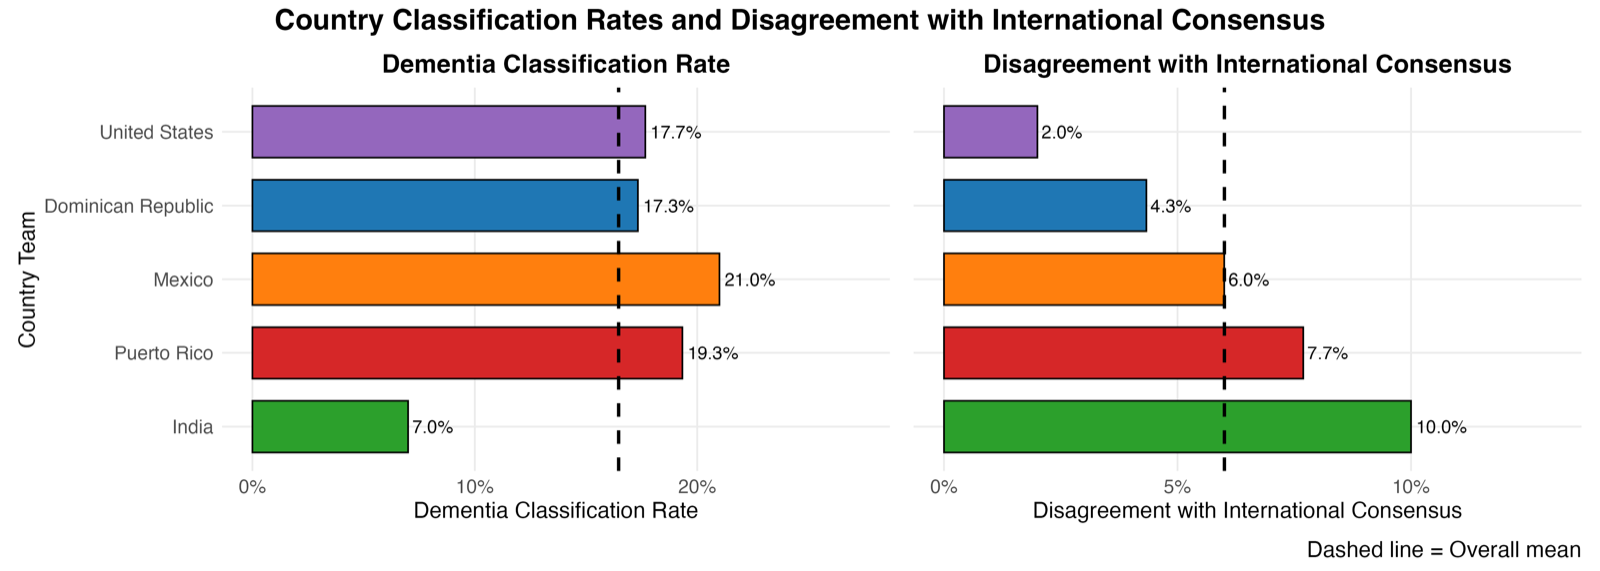
The short version: twenty-seven clinicians from five countries (the Dominican Republic, Mexico, Puerto Rico, the United States, and India) independently classified 300 older adults using CADAS survey data, applying a structured 10-question NIA-AA diagnostic algorithm through a web-based consensus platform. Each case was reviewed by at least three clinicians per country team, cases with within-country disagreement went to moderated consensus discussion, and international consensus was defined by majority rule across all five teams. The figure above gives a taste of the results: the country teams classified dementia at noticeably different rates, and their disagreement with the international consensus ranged from 2% (United States) to 10% (India). Getting clinicians on three continents to review the same evidence through one platform is as much a coordination problem as a clinical one, and seeing it work end to end was the most satisfying part of the project.
It was a pleasure meeting everyone there. London itself was a highlight (the whole city is like a museum), and I’m looking forward to presenting at AAIC again someday.
]]>Contact Informationchrissoria@berkeley.eduNew Preprint: Model Diversity Over Model Size — Unanimous LLM Ensembles Correct Over-Classification in Survey Coding2026-06-04T00:00:00-07:002026-06-04T00:00:00-07:00https://christophersoria.com/posts/2026/06/llm-ensembles-survey-coding-preprintI have a new preprint out on SocArXiv: Model Diversity Over Model Size: Unanimous LLM Ensembles Correct Over-Classification in Survey Coding. It’s a deep dive into one finding flagged in the CatLLM methods paper — that unanimous multi-model ensembling corrects over-classification — asking which ensemble ingredients actually drive the gain and where the gain shows up.
Abstract
Large language models are increasingly used to classify open-ended survey responses, but they systematically over-classify, assigning categories too liberally on ambiguous cases and producing high sensitivity but low precision. Drawing on the established principle that aggregating multiple noisy annotators outperforms any single annotator, we test whether ensembles of LLMs can correct this problem. Using four open-ended survey questions with human-coded ground truth (3,208 responses, 6 categories per question), we evaluate ensemble configurations across 16 models spanning three cost tiers and six providers.
Key Findings
Unanimous voting fixes the over-classification problem. On the most ambiguous categories, the false positive rate drops from 50% to 3% under unanimous agreement, and precision triples.
The gain concentrates where over-classification is worst. Subjectively ambiguous categories with fuzzy boundaries see large improvements; categories with clear criteria show no benefit. The pattern replicates across three independent datasets (UCNets, GoEmotions, the British Election Study).
Cross-provider model diversity is the active ingredient. Models from different providers make different errors on ambiguous cases, and consensus filters the idiosyncratic false positives. Temperature variation and within-family size scaling contribute essentially nothing.
Three cheap models can beat one expensive one. As few as three diverse lower-tier models suffice to reliably exceed GPT-5 on the ambiguous classification tasks where this matters most.
Implications
For the ambiguous classification problems common in open-ended survey research, the well-established annotation principle of multi-coder agreement transfers directly to LLMs: investing in diverse perspectives is more effective than investing in a single expensive model. Practically, this means survey researchers can often skip the frontier-tier subscription and instead orchestrate a small cross-provider ensemble — frequently at a fraction of the cost.
]]>Contact Informationchrissoria@berkeley.eduNew Preprint: High Agreement, Different Stories — How LLM Classifiers Reshape Demographic Patterns in Survey Data2026-06-02T00:00:00-07:002026-06-02T00:00:00-07:00https://christophersoria.com/posts/2026/06/llm-classifiers-demographic-patterns-preprintI have a new preprint out on SocArXiv: High Agreement, Different Stories: How LLM Classifiers Reshape Demographic Patterns in Survey Data. This is a substantially revised version of my earlier preprint, with new analyses centered on how high agreement rates can mask thematic and demographic divergence between LLM and human coders.
Abstract
What we learn from open-ended survey data depends on who—or what—does the coding. Large Language Models (LLMs) promise to democratize qualitative analysis, but do high agreement rates translate into equivalent thematic findings? This study compares eight LLMs to human annotators on a multilabel coding task using 3,200 responses from the UC Berkeley Social Networks Study, comprising over 19,000 coding decisions. Although LLM-human reliability does not match human-human reliability overall, LLMs approach human performance on simpler tasks and can serve as useful additional coders for generating consensus labels.
Key Findings
Compared to a gold-standard human consensus, models achieve 82–97% per-category agreement, but macro F1 is lower and response-level similarity is lower still: even the best model reproduces the full human label set for fewer than 60% of responses.
High agreement masks thematic divergence. Models systematically over-identify themes, assigning 67% more categories per response, especially for categories requiring greater interpretive judgment.
Models show lower agreement for some demographic groups. These gaps are partly explained by response characteristics such as length, clarity, and atypicality, and some persist after controls, with implications for studies of populations whose response styles diverge from the corpus average.
At the sample level, models largely preserve the overall thematic narrative: human and model category rankings correlate strongly (pooled Spearman’s ρ = 0.75), and top-performing models achieve approximately 80% directional agreement on demographic patterns.
Concrete behavioral questions—such as reasons for moving or strategies for making friends—show especially strong alignment, whereas more interpretive questions show greater divergence.
Implications
Systematic over-classification can still shift narratives about how specific groups behave, leading researchers to report patterns that the human gold standard does not support. LLMs can meaningfully reduce coding burden, but for studies sensitive to demographic nuance they are best treated as additional coders contributing to a human-anchored consensus rather than as drop-in replacements.
]]>Contact Informationchrissoria@berkeley.eduCatLLM Desktop: A Mac App for Classifying Text Without Writing Code2026-05-25T00:00:00-07:002026-05-25T00:00:00-07:00https://christophersoria.com/posts/2026/05/catllm-mac-desktop-app
CatLLM is an open-source Python and R toolkit for classifying open-ended text with large language models. For survey classification, the defaults are calibrated against the consensus of double-blind coding by sociologists and demographers across multiple datasets — yielding 88% to 99% agreement with human coders across 30+ LLMs depending on the task (Soria 2026). The same engine underlies separate packages for political text, social media, academic papers, and other domains, and the toolkit has been used in several academic research papers.
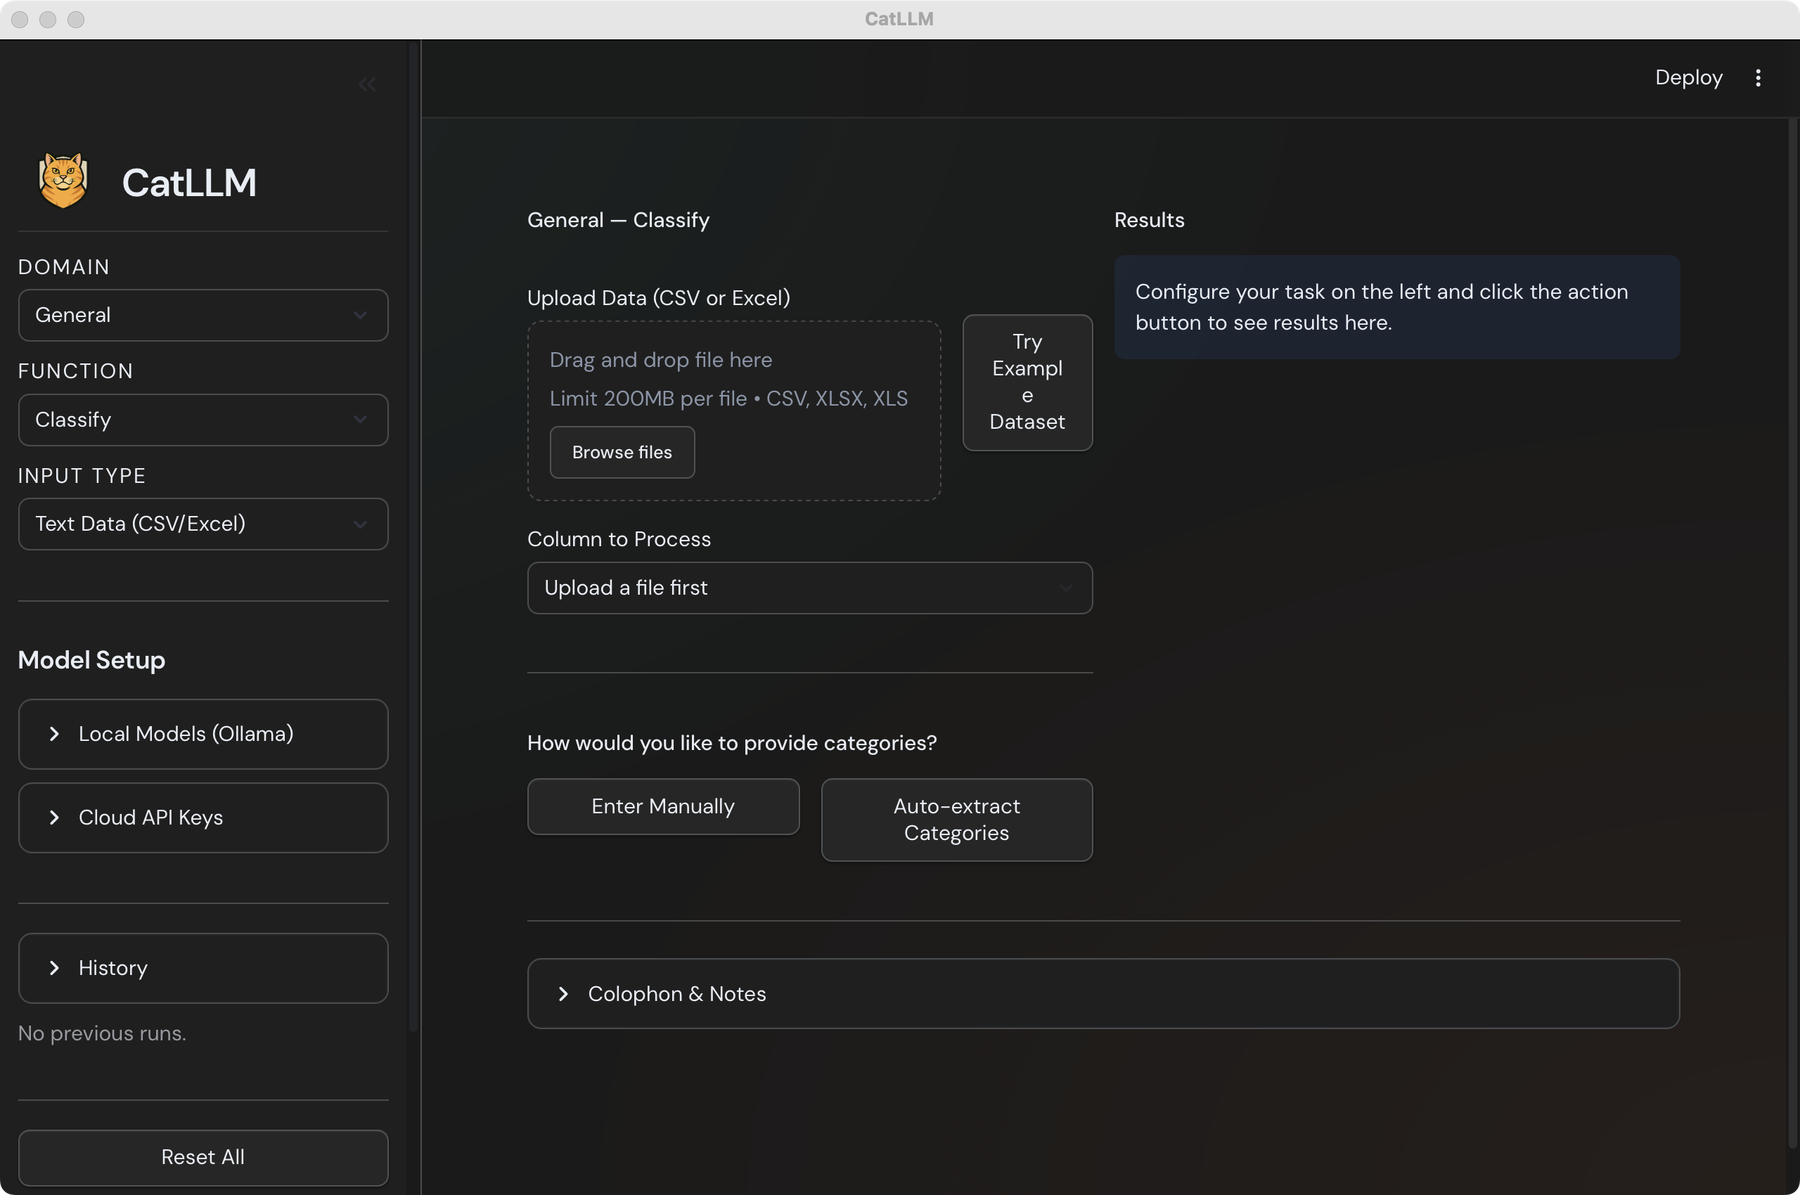
CatLLM Desktop is now available. The Mac app is the same cat-llm pipeline that powers the Python and R libraries, wrapped as a self-contained application — no Python install, no terminal, no reticulate, no API gymnastics. Drag in a CSV or Excel file, choose categories, and download a coded dataset. The Apple Silicon .dmg (286 MB) is on Hugging Face today, linked from the download section on catllm.com; Intel and Windows builds are planned. On first launch, macOS Gatekeeper will say it can’t check the app — right-click the app in Applications → Open → Open, and you can verify the download against the matching SHA-256.
The core workflow is a no-code classify-from-spreadsheet: pick a Domain (General, Survey, and so on) and a Function (Classify, Extract, Explore, Summarize) from the left sidebar, drop in a CSV or XLSX file up to 200 MB, choose the column you want coded, and either type your categories in directly or let the app auto-extract a candidate taxonomy from a sample of the data. Results appear on the right, ready to download as a CSV. The outputs are bitwise the same as what the Python library produces with the same configuration, which means anything coded in the app can be re-run later in code without re-validating the defaults.
Model setup exposes both paths the package supports: cloud API keys (OpenAI, Anthropic, Google) entered once and stored locally on the machine, or local models served by Ollama. The privacy implication matters for survey work — with Ollama, no response text ever leaves the laptop, which is the friction-free path for IRB-bound research, clinical text, or collaborators who can’t legally send respondent data to a vendor. The provider-agnostic engine underneath is the same as in the library, so swapping gpt-5 for qwen2.5:14b is a dropdown change, not a code change.
The piece that ties this back to the library is the Deploy button at the top right: it emits the equivalent Python (and R) script for whatever you configured in the GUI, so a classification run is not a black box. The script is reproducible — commit it to your repo, paste it into a paper’s supplement, or hand it to a co-author who already works in code. That’s the bridge the app is meant to be: collaborators without programming experience produce work that another team member can re-run, audit, and extend. Download the Mac app, or reach out at ChrisSoria@Berkeley.edu if you hit anything weird.
]]>Contact Informationchrissoria@berkeley.eduCatLLM R Package: Classify Survey Text with LLMs in R2026-05-17T00:00:00-07:002026-05-17T00:00:00-07:00https://christophersoria.com/posts/2026/05/cat-llm-r-packages
The CatLLM R package is now live. CatLLM started life as a Python package for classifying open-ended survey responses with LLMs, and it still is, but a lot of the researchers I want to reach work in R, not Python. Asking a sociologist or demographer to spin up a Python project just to categorize a column of text responses is a friction tax most won’t pay.
So I built the R layer. As of this week, eight R packages (cat.stack, cat.survey, cat.vader, cat.ademic, cat.cog, cat.pol, cat.web, and the cat.llm meta-package) are installable from r-universe. They wrap the Python CatLLM ecosystem via reticulate, expose the same classify(), extract(), explore(), and summarize() API, and return results bitwise-equivalent to the Python equivalents. There is no R-specific logic; it is a thin shim. But it means you can stay in your tidyverse pipeline.
Why a CatLLM R Package
A huge share of survey methodology, demography, sociology, political science, and public health work happens in R. The available options for those users have been (1) reticulate the Python package themselves, (2) round-trip data to a separate Python script, or (3) hand-code text by RA. The first is fiddly, the second is annoying, the third does not scale. A native R interface removes all three.
Not on CRAN yet. Install from r-universe for now. The packages are not on CRAN while the API stabilizes. R-universe is set up like an additional repo, so install.packages() works as usual.
Why the dot in cat.llm? R’s convention for multi-word package names uses a dot, like data.table or R.utils. The Python equivalents drop the dot (catllm, catstack, catsurvey, and so on). Use the dotted form in library() and install.packages().
install_cat_stack() runs once. Under the hood it calls pip install for the Python backend packages and configures reticulate to find them. After that you do not think about Python again.
A First Classification with a Local LLM
The simplest way to verify the install is to classify a handful of responses with a local Ollama model. No API key, no cloud calls, no per-token cost.
In a terminal:
ollama pull qwen2.5:14b # ~9 GB on disk, ~10 GB RAM to run
Then in R:
library(cat.survey)responses<-c("The new wellness program is great, I've been using it daily.","It's confusing and the app crashes constantly.","I haven't tried it yet but it sounds promising.")# Verbose category descriptions classify several percentage points# more accurately than short labels, especially for smaller local# models like Qwen 14B below.verbose_cats<-c("Positive: The respondent expresses satisfaction, approval, or favorable sentiment.","Negative: The respondent expresses dissatisfaction, frustration, or criticism.","Neutral: The respondent is factual, ambivalent, or does not express clear sentiment.","Other: The response does not fit any of the above categories.")results<-classify(input_data=responses,categories=verbose_cats,user_model="qwen2.5:14b",model_source="ollama")print(results)
You get back a data frame with one column per category and one row per response, a binary matrix ready to merge back into your main dataset. The Ollama server starts automatically the first time you call classify() with model_source = "ollama"; you do not have to manage ollama serve yourself.
To run the same example against a cloud model, swap model_source = "ollama" and user_model = "qwen2.5:14b" for user_model = "gpt-5" (or "claude-sonnet-4-6", "gemini-2.0-flash", etc.) and pass api_key = Sys.getenv("OPENAI_API_KEY"). Everything else stays the same.
The Eight R Packages
Each domain package depends on cat.stack (the shared classification engine) and adds parameters relevant to its data type.
The remaining packages (cat.survey, cat.vader, cat.pol, cat.stack) all share the same classify() / extract() / explore() / summarize() API; the vignettes show domain-tuned examples for each.
Verifying the R Package Install
After cloning the parent repo, this one command installs all eight R packages from local source, sets up the Python backends, and runs a minimal classification per package:
Expected output: 8 / 8 passed (0 failed, 0 skipped). CI runs the same script on every push.
Caveats
Not on CRAN yet. R-universe only while the API stabilizes.
Python ≥3.9 required.install_cat_stack() runs pip install under the hood; if you do not have Python, reticulate will prompt you to install miniconda.
For Ollama workflows, the Ollama binary is a separate download from ollama.com. Local 7B–14B models trail frontier cloud models by a few percentage points on classification accuracy, which is fine for most survey work but worth validating against a labeled subsample for high-stakes coding.
cat.cog is single-function for now. CERAD scoring on drawn-shape images. More cognitive instruments to come.
If you run into trouble installing, hit a confusing error from reticulate, or want to suggest a domain wrapper that does not exist yet, reach out at ChrisSoria@Berkeley.edu.
]]>Contact Informationchrissoria@berkeley.eduWhat California Cities Actually Legislate: Classifying Municipal Ordinances with cat-pol2026-03-22T00:00:00-07:002026-03-22T00:00:00-07:00https://christophersoria.com/posts/2026/03/catpol-ordinance-analysis
Local laws shape daily life in ways that most people never see — your rent, your commute, what gets built on the corner lot — but they’re written in dense legal language, buried in city clerk archives, and produced at a volume no individual can keep up with. San Diego alone has passed nearly 90,000 ordinances and resolutions. San Francisco adds dozens per month. Journalists cover the headline votes; researchers study federal legislation; but the vast majority of municipal lawmaking happens without any systematic analysis at all.
cat-pol is designed to close that gap. It’s an open-source Python package that pulls municipal ordinances, federal laws, executive orders, and political speech directly from public datasets, then uses LLMs to classify, summarize, and analyze them at scale. Built on top of cat-stack, it can take a 15,000-word ordinance written in statutory language and tell you, in plain English, what it does, who it affects, and where it falls on the political spectrum.
In this post, I used cat-pol to classify 200 recent ordinances each from San Diego and San Francisco — two major California cities with different political characters, against two classification schemes: a 12-category policy taxonomy and a 3-category political lean assessment. The goal: a quantitative snapshot of what these cities legislate about and whether the ideological differences between them show up in the text of their laws.
Want to run this on your own data? Skip to the methodology and replication section. The entire pipeline is open source and the datasets are public.
Background: cat-pol and the Data
cat-stack is a domain-agnostic LLM classification engine. cat-pol (pip install cat-pol) is its political text wrapper, shipping with 17 built-in political data sources on HuggingFace, including municipal ordinances from 12 California cities and counties, federal public laws, executive orders, presidential speeches, and Trump’s Truth Social posts, all accessible with a single source= parameter.
For this analysis, the data comes from two HuggingFace datasets:
Both datasets are scraped from official city clerk systems, include full ordinance text extracted from PDFs, and are updated weekly via automated scrapers. I took the 200 most recent ordinances with text from each city.
What follows is a demonstration of what you can learn from municipal legislation using a few lines of Python and no specialized legal knowledge. The entire analysis can be reproduced for free: the data is publicly hosted on HuggingFace, cat-pol is open source, and the classification can run on free-tier HuggingFace models or local models via Ollama with zero API costs. If you can write pip install cat-pol, you can replicate and extend every finding below.
San Francisco Passes Twice as Many Laws
Before asking what these cities legislate about, it’s worth asking how much they legislate.
San Diego
San Francisco
Ordinances per month (2020–2025 avg)
11.2
22.2
Ratio
2.0x
San Francisco passes roughly twice as many ordinances per month as San Diego: 22 vs 11. The pattern is stable across years, not a spike. SF consistently produces 20–25 ordinances per month; SD produces 9–15.
San Diego compensates with a high volume of resolutions (about 49 per month), which are administrative actions (contract approvals, budget items, proclamations) rather than new law. But in terms of actual lawmaking (text that creates, amends, or repeals municipal code), SF is substantially more productive.
This matters for everything that follows. When we compare the share of ordinances in each policy domain, we’re comparing slices of very different pies. A 24% business regulation rate in SF means roughly 5 new business ordinances per month. An 8% rate in SD means less than 1. Throughout the rest of this analysis, I’ll show both percentages and estimated monthly counts to keep the denominators honest.
What Do These Cities Legislate About?
Rather than imposing categories top-down, I used cat-pol’s extract() function to discover 12 policy domains directly from the ordinance text. Categories are multi-label, so a single ordinance can be tagged with multiple domains. See the methodology section for how the categories were generated and the full list.
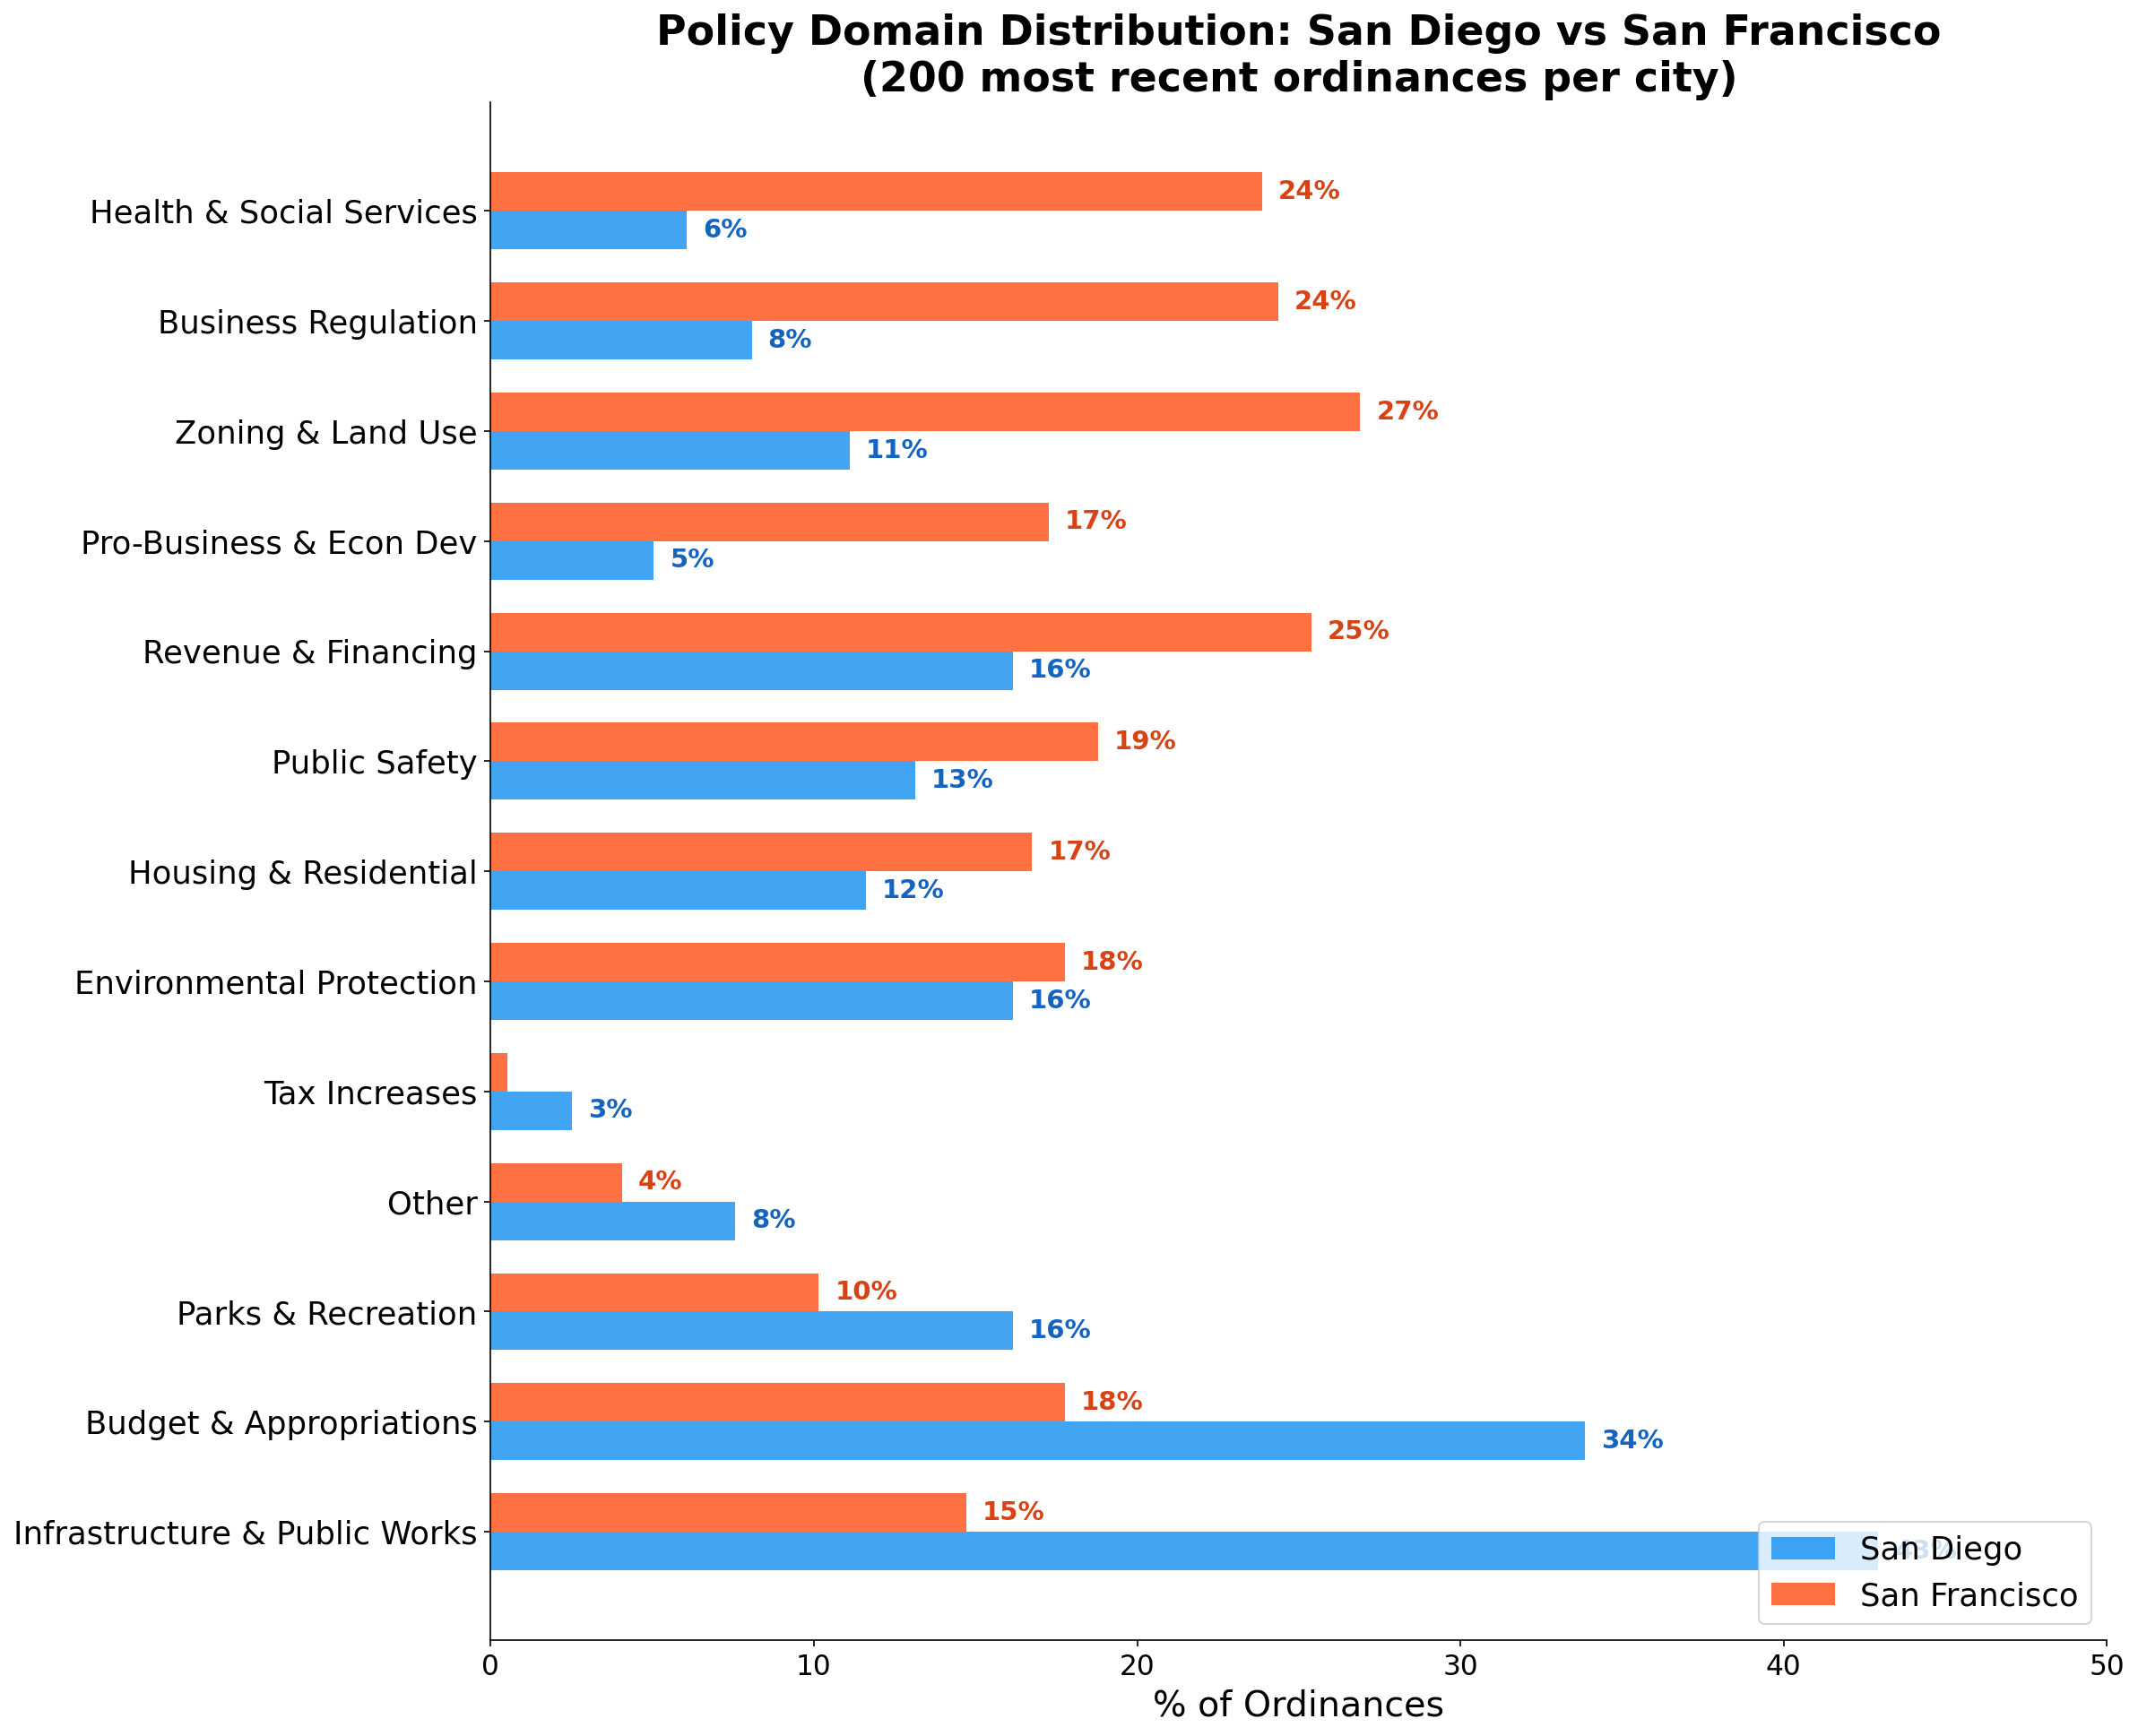
Results: Policy Domain Distribution
200 most recent ordinances per city. Multi-label (rows sum to >100%). Model: Qwen 2.5-72B-Instruct.
What the Numbers Mean
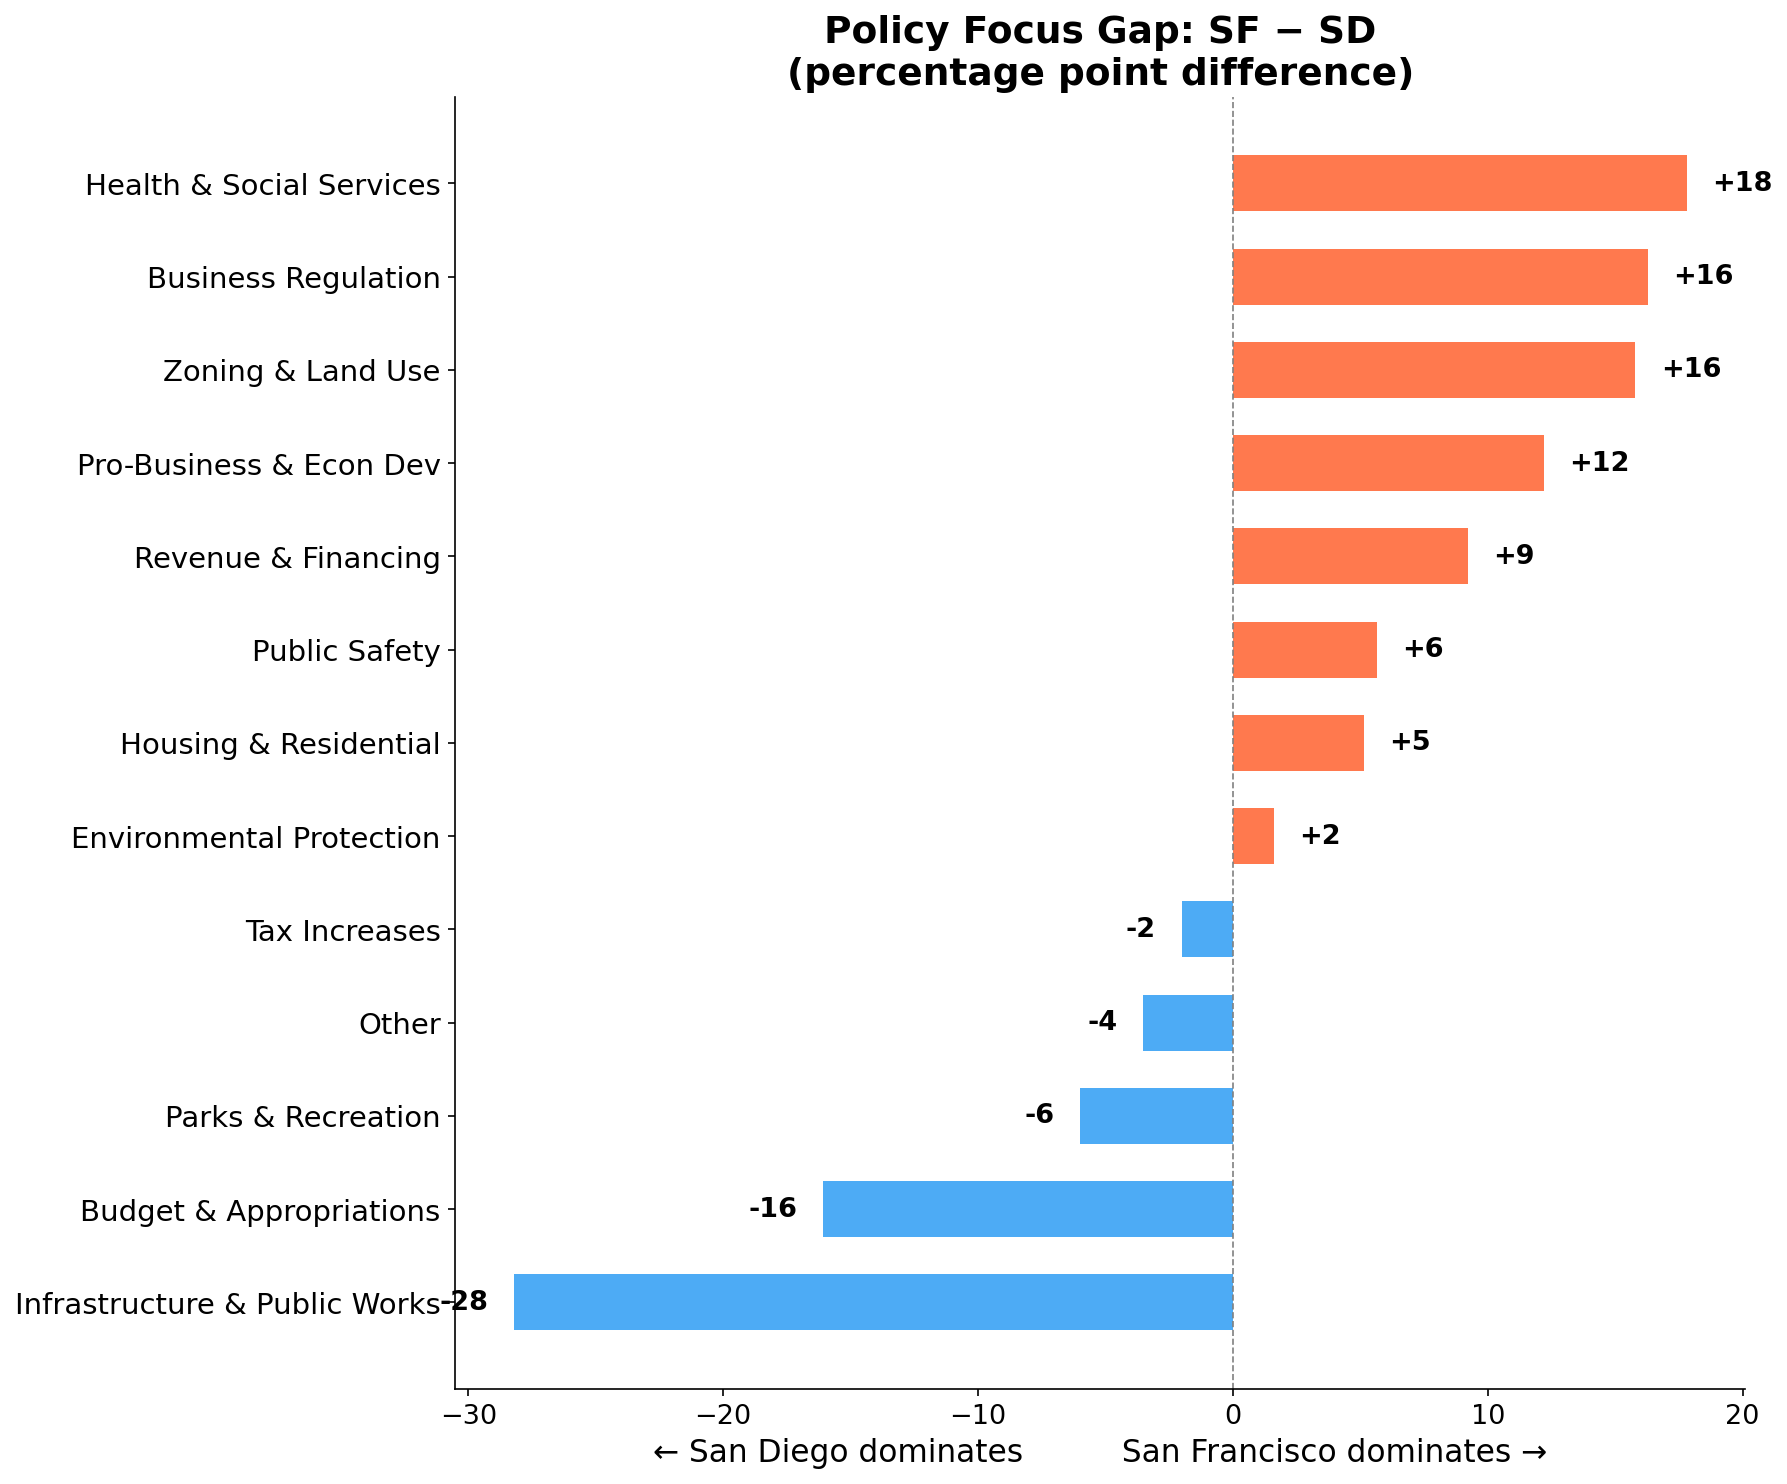
The two cities legislate about fundamentally different things.
San Diego is a building city. Nearly half (43%) of its recent ordinances touch infrastructure and public works: road improvements, water main replacements, sewer projects, construction contract extensions. Even though SD passes half as many ordinances overall, it still produces more infrastructure legislation per month in absolute terms than SF (4.8 vs 3.3). This isn’t just proportional: SD is genuinely more active on physical infrastructure than SF is. The same holds for parks (1.8 vs 2.3/month, close despite SD’s half-sized legislative output). SD’s legislative agenda reads like a city physically constructing and maintaining itself.
San Francisco is a regulating city. Its ordinances spread across a wider range of policy domains, with no single category exceeding 27%. The biggest concentrations are in zoning and land use (6.0/month), revenue and financing (5.6/month), and business regulation (5.4/month). Health and social services, a category that barely registers in San Diego at 0.7 ordinances per month, hits 5.3 per month in SF. That’s not a rounding difference; it’s a 7x gap. Housing policy runs at roughly triple SD’s rate (3.7 vs 1.3/month). San Francisco’s legislative output reads like a city managing social complexity: who can build what, under what conditions, with what protections for whom.
The environmental protection rate is nearly identical between the two cities (~17%), suggesting this is a baseline concern for California municipalities regardless of political character. Tax increases are rare in both (under 3%), which likely reflects the political difficulty of explicit tax votes at the local level.
SF legislates more about business in both directions. San Francisco scores higher than San Diego on business regulation (24% vs 8%) and pro-business/economic development (17% vs 5%). It creates more rules and more incentives. San Diego’s approach to business is to leave it alone. The legislative silence is itself a policy choice.
SF actively raises revenue to fund social programs. SF generates 25% of its ordinances around revenue and financing, compared to SD’s 16%. Combined with SF’s 24% rate on health and social services (vs SD’s 6%), the picture is a city that raises money to fund an interventionist social agenda. San Diego raises less and spends what it raises on concrete: roads, pipes, parks.
Put differently: San Diego legislates like a city that wants to run well. San Francisco legislates like a city that wants to do good. Whether “doing good” through regulation and social programs actually produces better outcomes is a separate empirical question, but the legislative priorities are unmistakable in the data. SD’s council spends its time keeping the lights on and the water flowing. SF’s council spends its time deciding who gets housing protections, which businesses need new permits, and how to fund homelessness services.
As a robustness check, I re-ran the analysis on 1,000 ordinances per city using GPT-4o with a different, data-driven category scheme. Different model, five times the sample, looser categories. Same conclusion: SD dominates on infrastructure and construction; SF dominates on health, environment, and housing. The pattern holds.
Part 2: Do Ordinances Have a Political Lean?
Category Setup
For the political lean analysis, I used three categories designed to capture ideological orientation:
Conservative/Right-Leaning Policy — deregulation, tax cuts, pro-business measures, law enforcement expansion, property rights protections, reduced government intervention, privatization of services
Progressive/Left-Leaning Policy — new regulations, tax increases, tenant protections, environmental mandates, social services expansion, equity/inclusion initiatives, labor protections, police reform
Neutral — routine contract approvals, procedural amendments, election scheduling, civil service appointments, budget housekeeping with no policy direction
This classification used Qwen3-235B, the flagship thinking model, to see whether reasoning capability helps with the more nuanced task of ideological classification.
Results: Political Lean Distribution
San Diego
San Francisco
Conservative/Right-Leaning
2.6%
23.1%
Progressive/Left-Leaning
19.9%
31.8%
Neutral
77.6%
45.6%
200 most recent ordinances per city. Multi-label classification. Model: Qwen3-235B (thinking model).
The results are counterintuitive, and that’s what makes them interesting.
San Diego’s ordinances are overwhelmingly neutral. Nearly 78% of SD’s recent ordinances carry no detectable ideological lean. These are contract extensions, budget transfers, construction authorizations. The machinery of a city that governs by administration rather than ideology. Only 3% code as conservative and 20% as progressive.
San Francisco legislates politically in both directions. SF has a higher progressive rate (32% vs 20%), which aligns with expectations. But the surprise is SF’s conservative rate: 23% vs SD’s 3%. San Francisco produces nearly 9x more conservative-coded ordinances than San Diego.
This isn’t because San Francisco has a secret conservative agenda. It’s because SF actively legislates about the domains that register as ideological: business regulation, tax policy, development incentives, policing. When you pass an ordinance streamlining permits for small businesses, that codes as pro-business/conservative. When you pass an ordinance adding tenant protections, that codes as progressive. San Diego doesn’t pass either ordinance. It passes a contract amendment instead.
The neutral rate tells the real story. SD’s 78% neutral rate means its city council spends most of its time on administrative governance. SF’s 46% neutral rate means less than half of its legislative output is purely procedural. The majority of SF ordinances take a policy stance of some kind. SF doesn’t just lean left — it legislates ideologically, period. It takes more stances in more directions than San Diego takes in any direction.
Methodology Notes
A few important details about how this analysis works and where it might break.
Multi-label classification. Each ordinance can be tagged with multiple categories simultaneously. An infrastructure bond gets both “Infrastructure” and “Revenue and Financing.” This means percentages sum to more than 100%. That’s by design, not a bug.
Model choice. I used two models: Qwen 2.5-72B-Instruct for the 12-category policy domain classification and Qwen3-235B (a 235-billion parameter mixture-of-experts thinking model) for the political lean analysis. Both are open-source models accessed via HuggingFace’s inference API, no OpenAI dependency. The robustness check used GPT-4o on a larger sample to confirm the results hold across model families.
Category discovery. Categories weren’t hand-picked. I used pol.extract() to sample 50 ordinances and let the LLM discover recurring themes, then semantically merged duplicates into a clean taxonomy. The specificity="specific" parameter ensures category names include examples, which significantly improves classification accuracy over bare labels. The 12 policy domain categories used:
Tax Increases 2. Revenue and Financing 3. Budget and Appropriations 4. Housing and Residential Development 5. Zoning and Land Use Changes 6. Infrastructure and Public Works 7. Business Regulation 8. Pro-Business and Economic Development 9. Environmental Protection 10. Public Safety 11. Health and Social Services 12. Parks, Recreation, and Culture
For the political lean analysis, three categories: Conservative/Right-Leaning Policy, Progressive/Left-Leaning Policy, and Neutral.
Limitations. There’s no ground truth here — no human-coded comparison set for municipal ordinances. The classifications reflect what the model thinks these ordinances are about, not an objective standard. Model bias is a real concern, especially for the political lean analysis; LLMs have known tendencies in how they interpret political language. The sample sizes (200 for the Qwen runs, 1,000 for the GPT-4o robustness check) are reasonable but not exhaustive. The full classified datasets (1,700 SD ordinances, 3,900 SF ordinances) are now public on HuggingFace for anyone who wants to validate or extend this analysis.
The Public Datasets
All data and classification results are publicly available:
San Francisco ordinances: chrissoria/sf-ordinances (4,048 records)
The source registry includes 17 datasets across California cities and counties, federal legislation, and social media:
importcat_polaspolpol.list_sources()# see all 17 sources
How to Run It Yourself
pip install cat-pol
importcat_polaspol# Discover categories from your data
categories=pol.extract(source="city_san_diego",doc_type="ordinance",n=50,api_key="your-key",user_model="Qwen/Qwen2.5-72B-Instruct",model_source="huggingface",max_categories=12,specificity="specific",)# Classify using discovered categories
results=pol.classify(source="city_san_diego",categories=categories["top_categories"],doc_type="ordinance",n=200,api_key="your-key",user_model="Qwen/Qwen2.5-72B-Instruct",model_source="huggingface",)# Summarize in plain language
summaries=pol.summarize(source="city_san_diego",n=10,format="bullets",tone="eli5",api_key="your-key",)# Optimize prompts with user feedback
result=pol.prompt_tune(source="city_san_diego",categories=["Housing","Public Safety","Finance"],api_key="your-key",sample_size=15,)# Fetch raw data (no API key needed)
df=pol.fetch_source("city_san_diego",n=100,doc_type="ordinance")
cat-pol handles the data pull, classification, and output in a consistent pipeline. Every dataset in the registry uses the same source= parameter across all five functions (classify, extract, explore, summarize, prompt_tune) plus fetch_source and list_sources.
What This Tells Us
The consistent finding across every analysis (different models, different sample sizes, different category schemes) is that San Diego and San Francisco govern in fundamentally different modes.
San Diego governs through administration: infrastructure projects, contract management, budget operations. Its ordinances are largely neutral, procedural, and focused on keeping the physical city running. When SD does legislate on policy, it tilts modestly progressive, but most of its legislative energy goes to the apolitical work of urban maintenance.
San Francisco governs through policy: zoning, business regulation, health services, housing, environmental mandates. Its ordinances are more likely to carry an ideological valence, progressive and conservative — because SF actively codifies political values into law. It produces twice as many ordinances per month, and more than half of them take a policy stance.
Neither mode is inherently better. SD’s approach keeps government lean and focused; SF’s approach uses legislation as a tool for social intervention. But the data makes clear that these aren’t just different political leanings. They’re different theories of what city government is for.
What’s Next
This analysis covers two cities. cat-pol ships with 17 data sources (and growing): 12 California cities, San Diego County, federal public laws, executive orders, presidential speeches, and Trump’s Truth Social posts. The same classification pipeline can be applied to any of them. Some questions I haven’t answered:
Time series: Has SF always been this regulatory, or did it shift after a particular election?
City-size effects: Do smaller cities (Salinas, Clovis) look more like SD or SF?
County vs city: SD County just went live as a dataset — does county governance look different from city governance in the same jurisdiction?
Federal comparison: How do municipal policy domains map onto federal legislation?
]]>Contact Informationchrissoria@berkeley.eduUpcoming Presentations and Conferences (Summer–Fall 2026)2026-03-13T00:00:00-07:002026-03-13T00:00:00-07:00https://christophersoria.com/posts/2026/03/upcoming-presentations-2026I have a busy conference season ahead. Here is where I’ll be presenting and what I’ll be talking about.
PAA 2026 — St. Louis, May 9
AAPOR 2026 — Los Angeles, May 13. Oral presentation on the CatLLM pipeline for LLM-based survey response classification.
EdDem Workshop — UW-Madison, May 14–15
Sunbelt 2026 — Daytona Beach, June 22–28. Oral presentation on social isolation, loneliness, and cognitive decline.
AAIC 2026 — London, July 12. Gateway/HCAP consensus session on the CADAS study, examining cross-national differences in web-based dementia diagnosis across clinician teams from five countries.
ECMTB 2026 — Graz, Austria, July 13–17. Minisymposium on advances in modeling human behavior and infectious disease spread.
ASA 2026 — New York, August 7–11 (pending)
ΨMCA 2026 — August 9–14. Presentation on algorithmic classification in dementia research.
Stata Conference 2026 — Boston, October 1. Poster on the CatLLM Stata package for LLM-assisted coding of open-ended survey text. Shared in the conference proceedings rather than presented in person.
USC Gateway Brownbag — Fall semester
GSA 2026 — National Harbor, MD, November 4–7 (pending)
The presentations span all three of my research streams: networks and cognitive aging (Sunbelt), computational methods for survey research (AAPOR), and applying algorithmic classification to dementia research (ΨMCA). If you’ll be at any of these, I’d love to connect.
]]>Contact Informationchrissoria@berkeley.eduWhat Bluesky’s Most-Followed Accounts Actually Post About2026-03-05T00:00:00-08:002026-03-05T00:00:00-08:00https://christophersoria.com/posts/2026/03/catvader-bluesky-analysis
A few days ago I used cat-vader to analyze my own Threads feed — 582 posts, 9 categories, and a slightly uncomfortable amount of self-reflection. That analysis asked a personal question: what do I post about?
This one asks a broader question. I took the same classification pipeline and pointed it at ten of Bluesky’s most-followed accounts: AOC, Mark Cuban, Mark Hamill, The Onion, George Takei, The New York Times, Rachel Maddow, Stephen King, MeidasTouch, and NPR. These accounts span the ecosystem — a sitting congresswoman, a billionaire, a pop culture icon, a satirical news outlet, two major media organizations, an advocacy network, and a horror novelist. 250 posts per account, 2,500 posts total, all classified by GPT-4o-mini against a nine-category scheme.
What do Bluesky’s most-followed accounts post about? And more interestingly: once you control for who is posting, does content type actually predict engagement?
Background: cat-vader and the Dataset
cat-vader is a fork of my open-source survey classification package cat-llm, adapted for social media analysis. The core idea is simple: you give it a list of posts and a set of categories with descriptions, and it uses an LLM to check each post against each category independently. Because categories aren’t mutually exclusive, a single post can belong to multiple categories simultaneously — a Rachel Maddow post about deportation policy might be tagged as both Politics & Elections and Social Issues & Justice. That multi-label design is what makes the output useful for analysis rather than just binning.
For this analysis I pulled 250 posts from each of ten accounts using cat-vader’s sm_source="bluesky" integration, classified them all using GPT-4o-mini, and exported everything to a single CSV that’s now publicly available on Hugging Face at chrissoria/bluesky-top10-classified.
One important note before diving in: Bluesky’s API returns views = 0 for all posts. The platform either doesn’t track impression counts or doesn’t expose them. That means the engagement analysis here focuses entirely on likes and replies — two signals that are real and public, but not the same as reach.
Category Setup
Before running classification, I defined nine categories designed to capture the thematic range of these accounts. Rather than bare labels, each category gets a description that guides the model on borderline cases.
1. Politics & Elections — Posts about electoral dynamics, political parties, voting, candidates, or partisan maneuvering. Includes commentary on legislative proceedings, election results, and the behavior of political figures as political actors.
“I honestly believe our most powerful position in a toxic time that feeds on cynicism, apathy, & despair is to genuinely care and act for a better world.” — Alexandria Ocasio-Cortez (146,230 likes)
2. Trump & MAGA Criticism — Posts directly targeting Donald Trump, his administration, his supporters, or the MAGA movement. Includes both policy critiques and character commentary.
“Trump Suffers Setback Unrelated To Child Rape” — The Onion (10,746 likes)
3. Social Issues & Justice — Posts about systemic inequality, civil rights, immigration enforcement, discrimination, or other social conditions. Focus is observational or normative rather than electoral.
“The owners of a Dallas County warehouse that ICE had planned to use as a mega detention center said Monday it will not sell or lease the property to the federal government. ‘God answered our prayers,’ the Hutchins Mayor said.” — Rachel Maddow (21,132 likes)
4. News & Current Events — Posts reporting on, linking to, or discussing recent news stories across any domain. Includes breaking news, investigative stories, and news aggregation.
“An NPR investigation finds the public database of Epstein files is missing dozens of pages related to sexual abuse accusations against President Trump.” — NPR (10,185 likes)
5. Entertainment & Pop Culture — Posts about film, television, music, celebrity, sports, books, or cultural moments. Includes personal fandom and cultural commentary.
“Bluesky is collegial and interesting, the way Twitter used to be. Bonus: most people can spell.” — Stephen King (80,664 likes)
6. Humor & Satire — Posts that are primarily comedic in intent: jokes, satirical takes, absurdist commentary, or ironic framings of current events.
“Netanyahu Calls Iran Strikes Necessary To Prevent War He Just Started” — The Onion (23,571 likes)
7. Science & Technology — Posts about scientific findings, technology developments, AI, climate science, medicine, or the intersection of tech and society.
8. Economy & Business — Posts about financial markets, economic conditions, corporate news, consumer prices, trade policy, or business developments.
“Mr. Cuban — I just wanted to quickly thank you. My husband has [cancer]. We went to pick up his medication and were informed it was $29,000. We were able to get it from CostPlus for $99.” — Mark Cuban (12,276 likes)
9. Personal & Lifestyle — Posts that are personal in nature: life updates, reflections, expressions of mood, personal milestones, or non-political opinion.
“We were married on this day in 1978… soulmates ever since.” — Mark Hamill (53,889 likes)
What Bluesky’s Top Accounts Post About
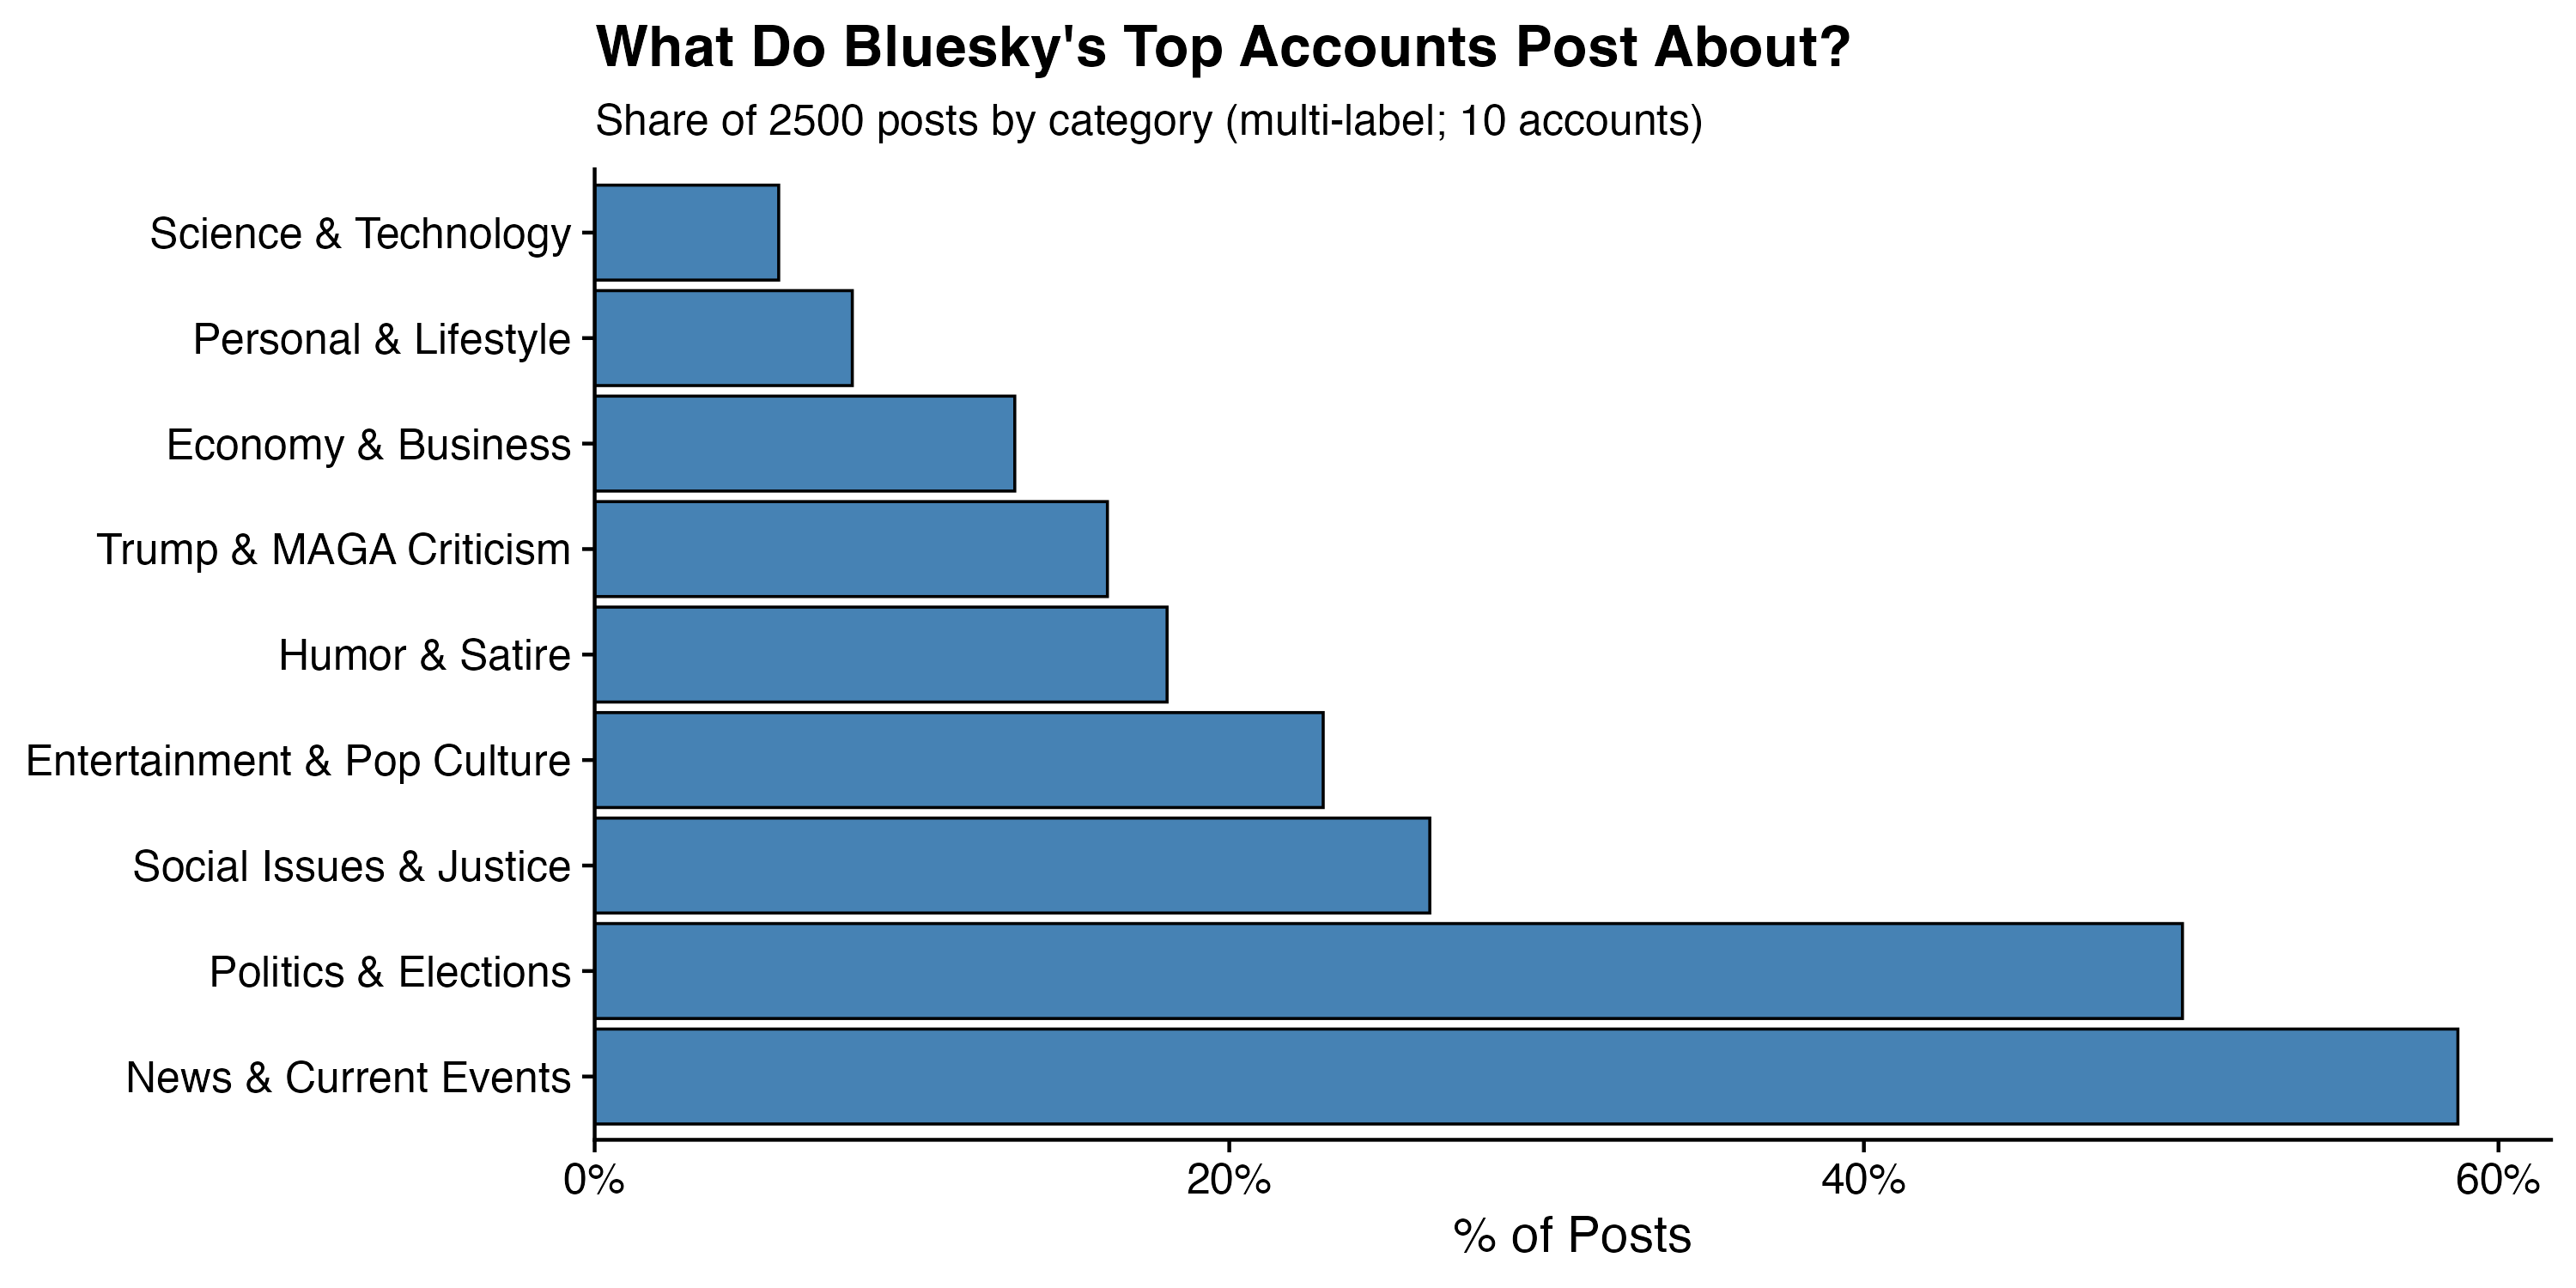
The overall landscape has a clear hierarchy. News & Current Events dominates at 58.7% of all 2,500 posts — nearly three in five posts link to or discuss a recent story. Politics & Elections comes in second at 50.0%, meaning half of all posts across these accounts touch on politics in some form. Then there’s a significant drop to Social Issues & Justice (26.3%), Entertainment & Pop Culture (23.0%), and Humor & Satire (18.0%). Trump & MAGA Criticism sits at 16.2%. At the bottom: Economy & Business (13.2%), Personal & Lifestyle (8.1%), and Science & Technology (5.8%).
The concentration at the top isn’t surprising for this particular set of accounts — these aren’t lifestyle influencers or tech reviewers. But the degree of dominance by News and Politics is still striking. More than half of what this slice of Bluesky produces is essentially political journalism or political commentary.
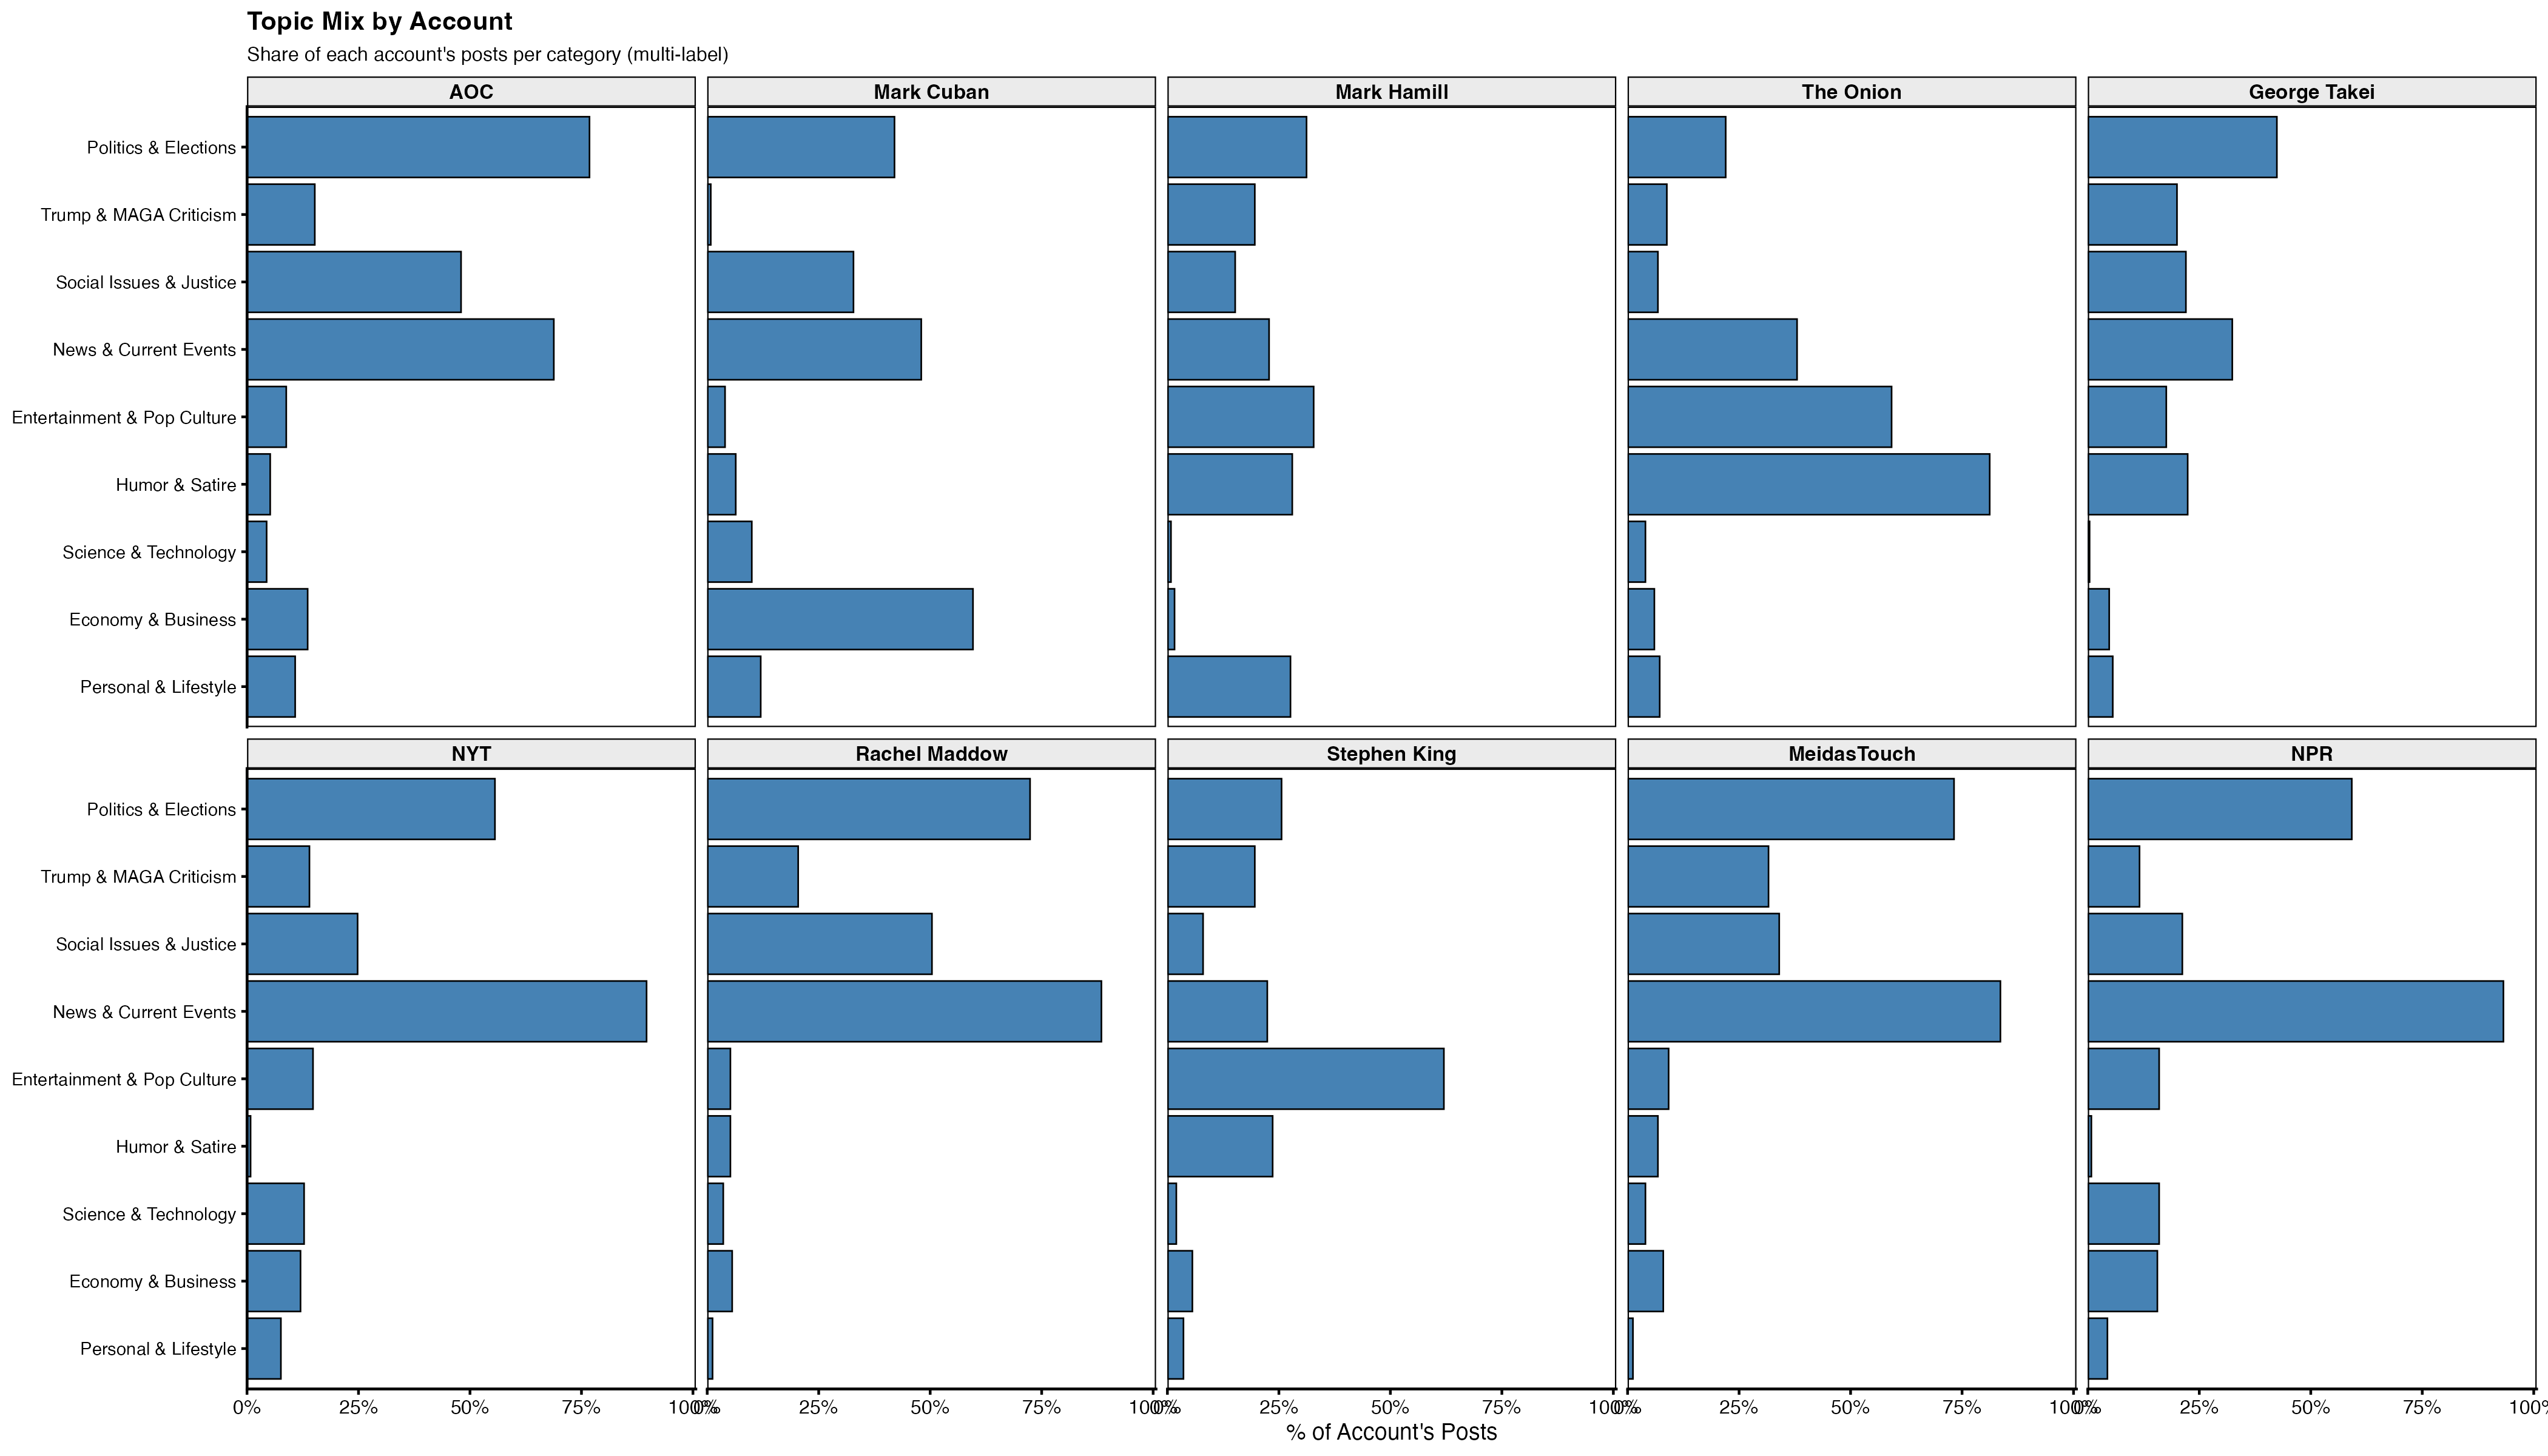
The account-level breakdown is where things get interesting.
NPR is the most single-mindedly focused: 93% of its posts fall under News & Current Events, and 60% under Politics & Elections. Almost nothing else. The Humor & Satire bar is essentially invisible (1%). NPR’s Bluesky presence is a straight news wire.
The Onion is the mirror image in the best way. 81% of Onion posts are tagged Humor & Satire — the highest satire rate of any account — but also 60% Entertainment & Pop Culture. What’s slightly surprising is that only 21% of The Onion’s posts are tagged Politics & Elections directly, and only 9% Trump & MAGA Criticism. Satirical headlines about Trump do get tagged politics when the framing is explicitly electoral, but a lot of Onion content uses political subjects in the service of pure absurdism, which the model correctly separates out.
AOC leads in Politics & Elections (68% of her posts), Social Issues & Justice (36%), and News & Current Events (55%). Almost no Humor, very little Economy. Her Bluesky presence reads like exactly what it is: a member of Congress doing political communication full-time.
Mark Cuban is the biggest outlier in the dataset. He’s the only account where Economy & Business is the dominant theme at 58% — more than any other category. He’s also one of the few accounts where Trump & MAGA Criticism is near zero (under 1%). Cuban posts about healthcare costs, business models, tariff economics, and policy mechanics. His account has almost nothing in common with the others topically.
Stephen King is the most balanced. He mixes Entertainment & Pop Culture (62%), Politics & Elections (27%), Humor & Satire (23%), and News & Current Events (24%) roughly evenly. His account feels like a person who actually posts about many things, not a media organization running a content strategy.
Mark Hamill tilts heavily toward Entertainment & Pop Culture (based on his posting about Star Wars, his marriage, personal reflections) alongside Politics — a mix that reflects his public persona as both a cultural figure and a vocal political voice.
Who Gets the Most Engagement?
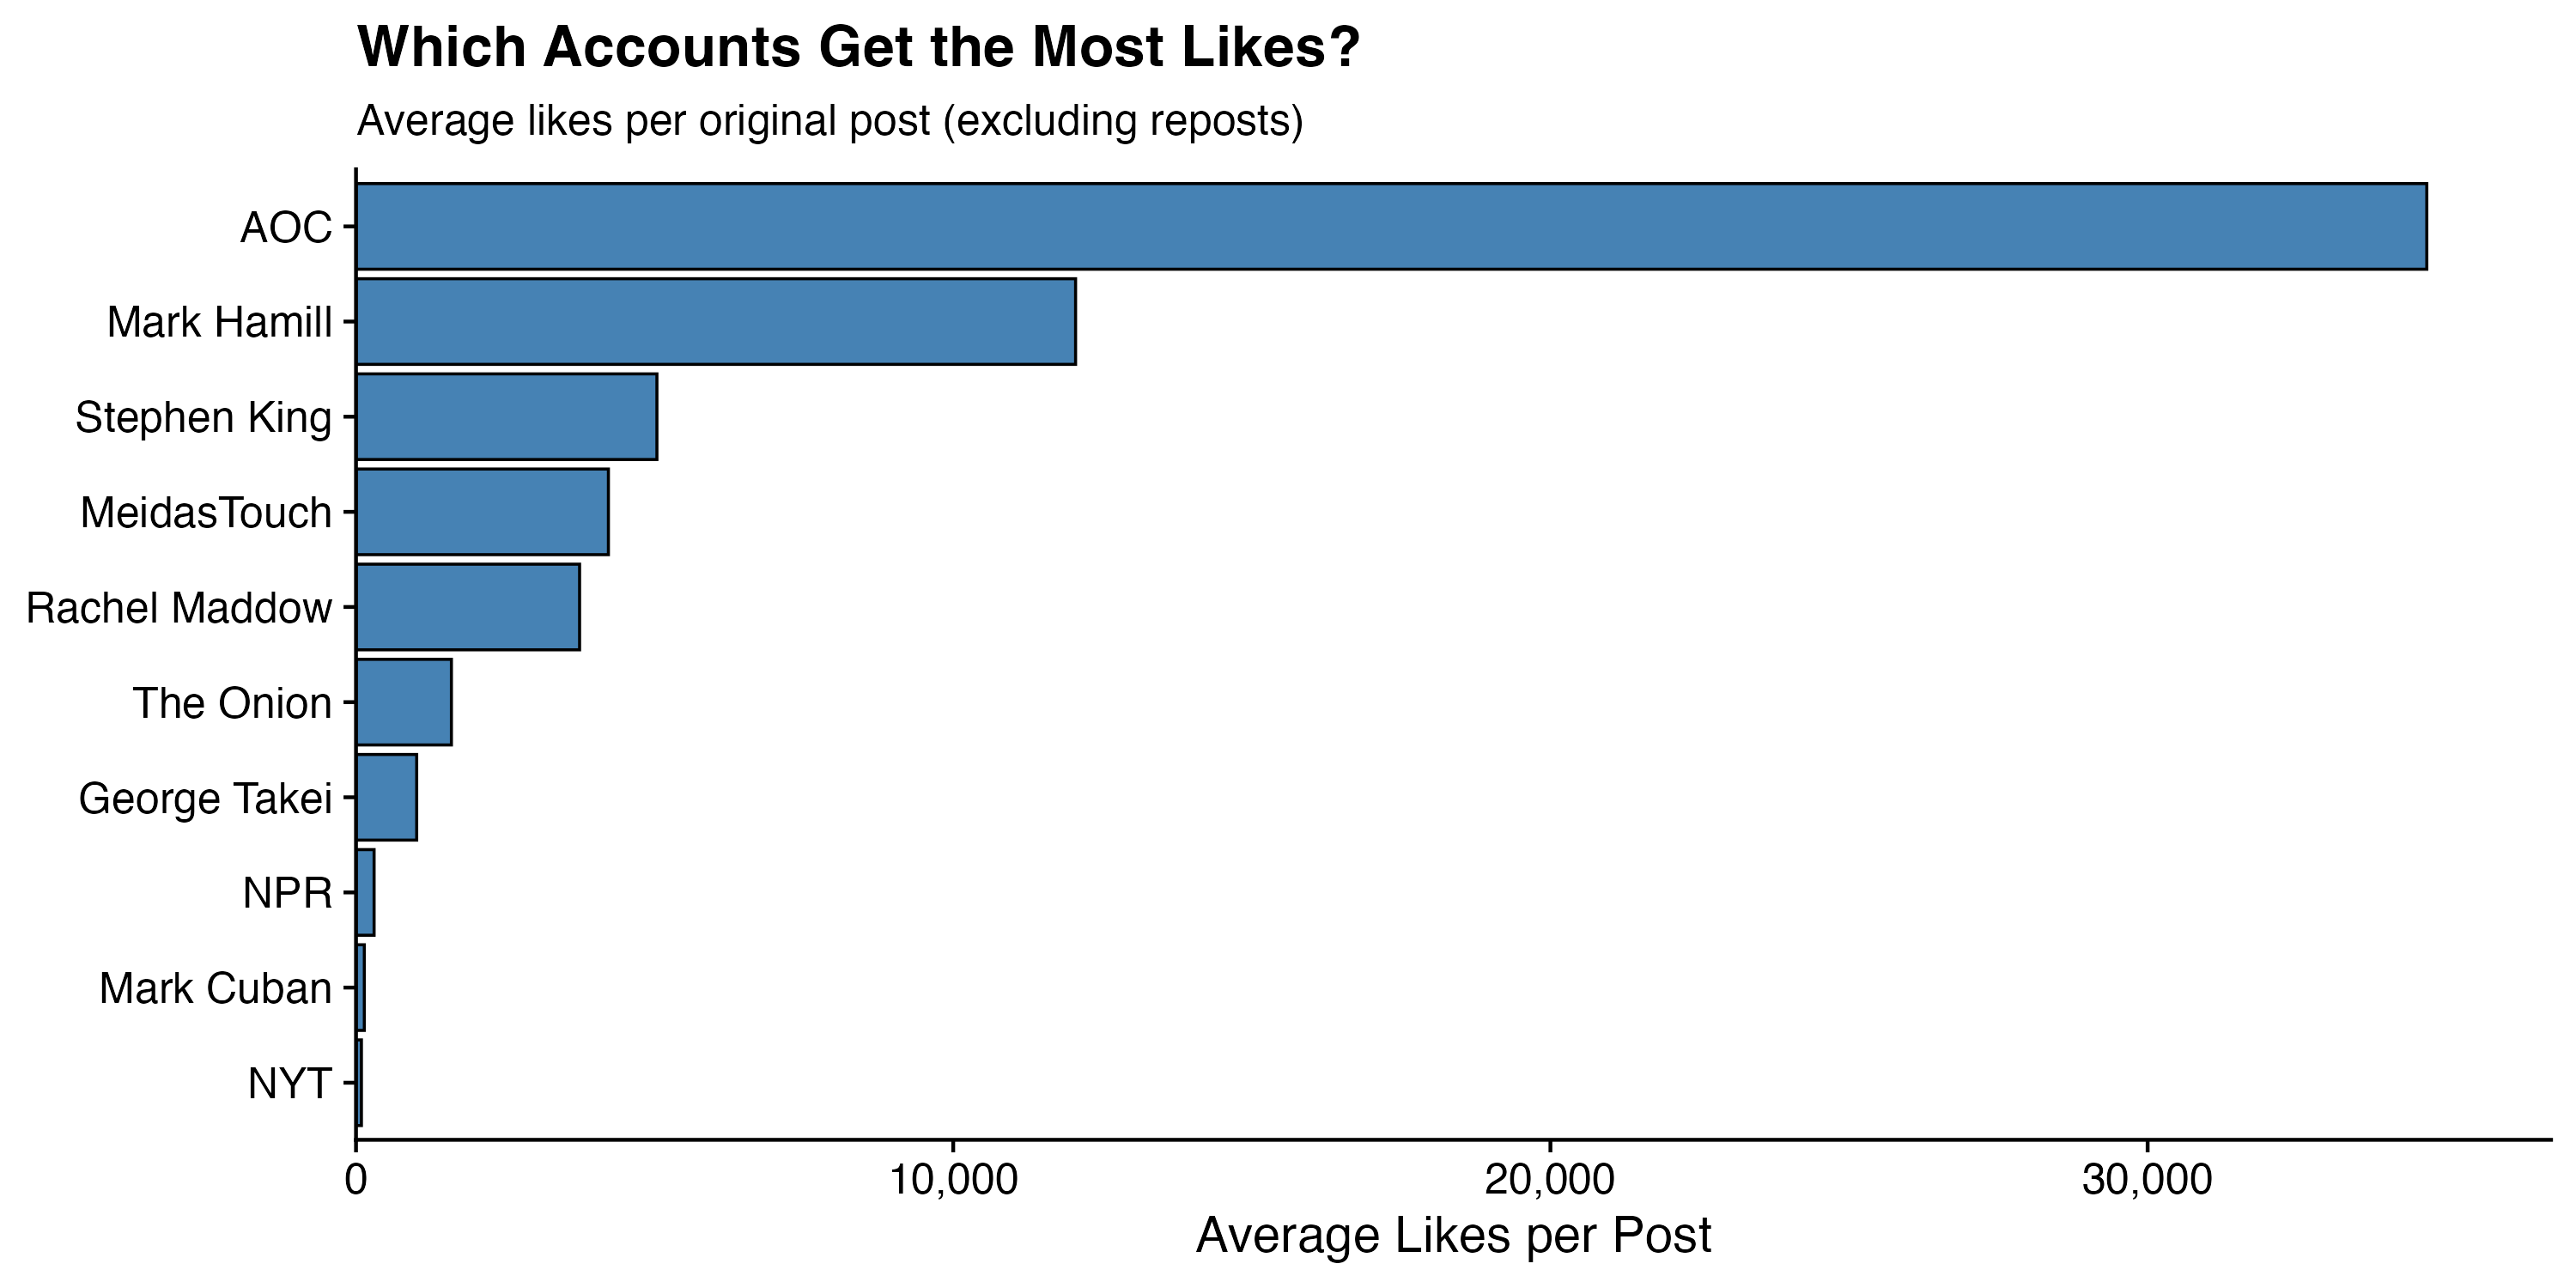
There is not a close race here. AOC averages 34,674 likes per post — more than twice the second-place Mark Hamill at 12,049. After that: Stephen King (5,039), MeidasTouch (4,226), Rachel Maddow (3,744), The Onion (1,598), George Takei (1,016), NPR (303), Mark Cuban (139), and NYT at 91.
The top 10 most-liked posts in the dataset are all AOC’s, with the most-liked reaching 167,305 likes on a post about a protest in Tucson: “Original projected attendance was 3,000 people. 23,000 showed up.”
The NPR and NYT numbers are particularly striking — both major media organizations with massive follower counts, but averaging under 300 and 100 likes per post respectively. The media organizations are generating engagement on Bluesky at a fraction of the rate of individual personalities. Whether that reflects the algorithm, audience behavior, content style, or all three is hard to disentangle from this data alone.
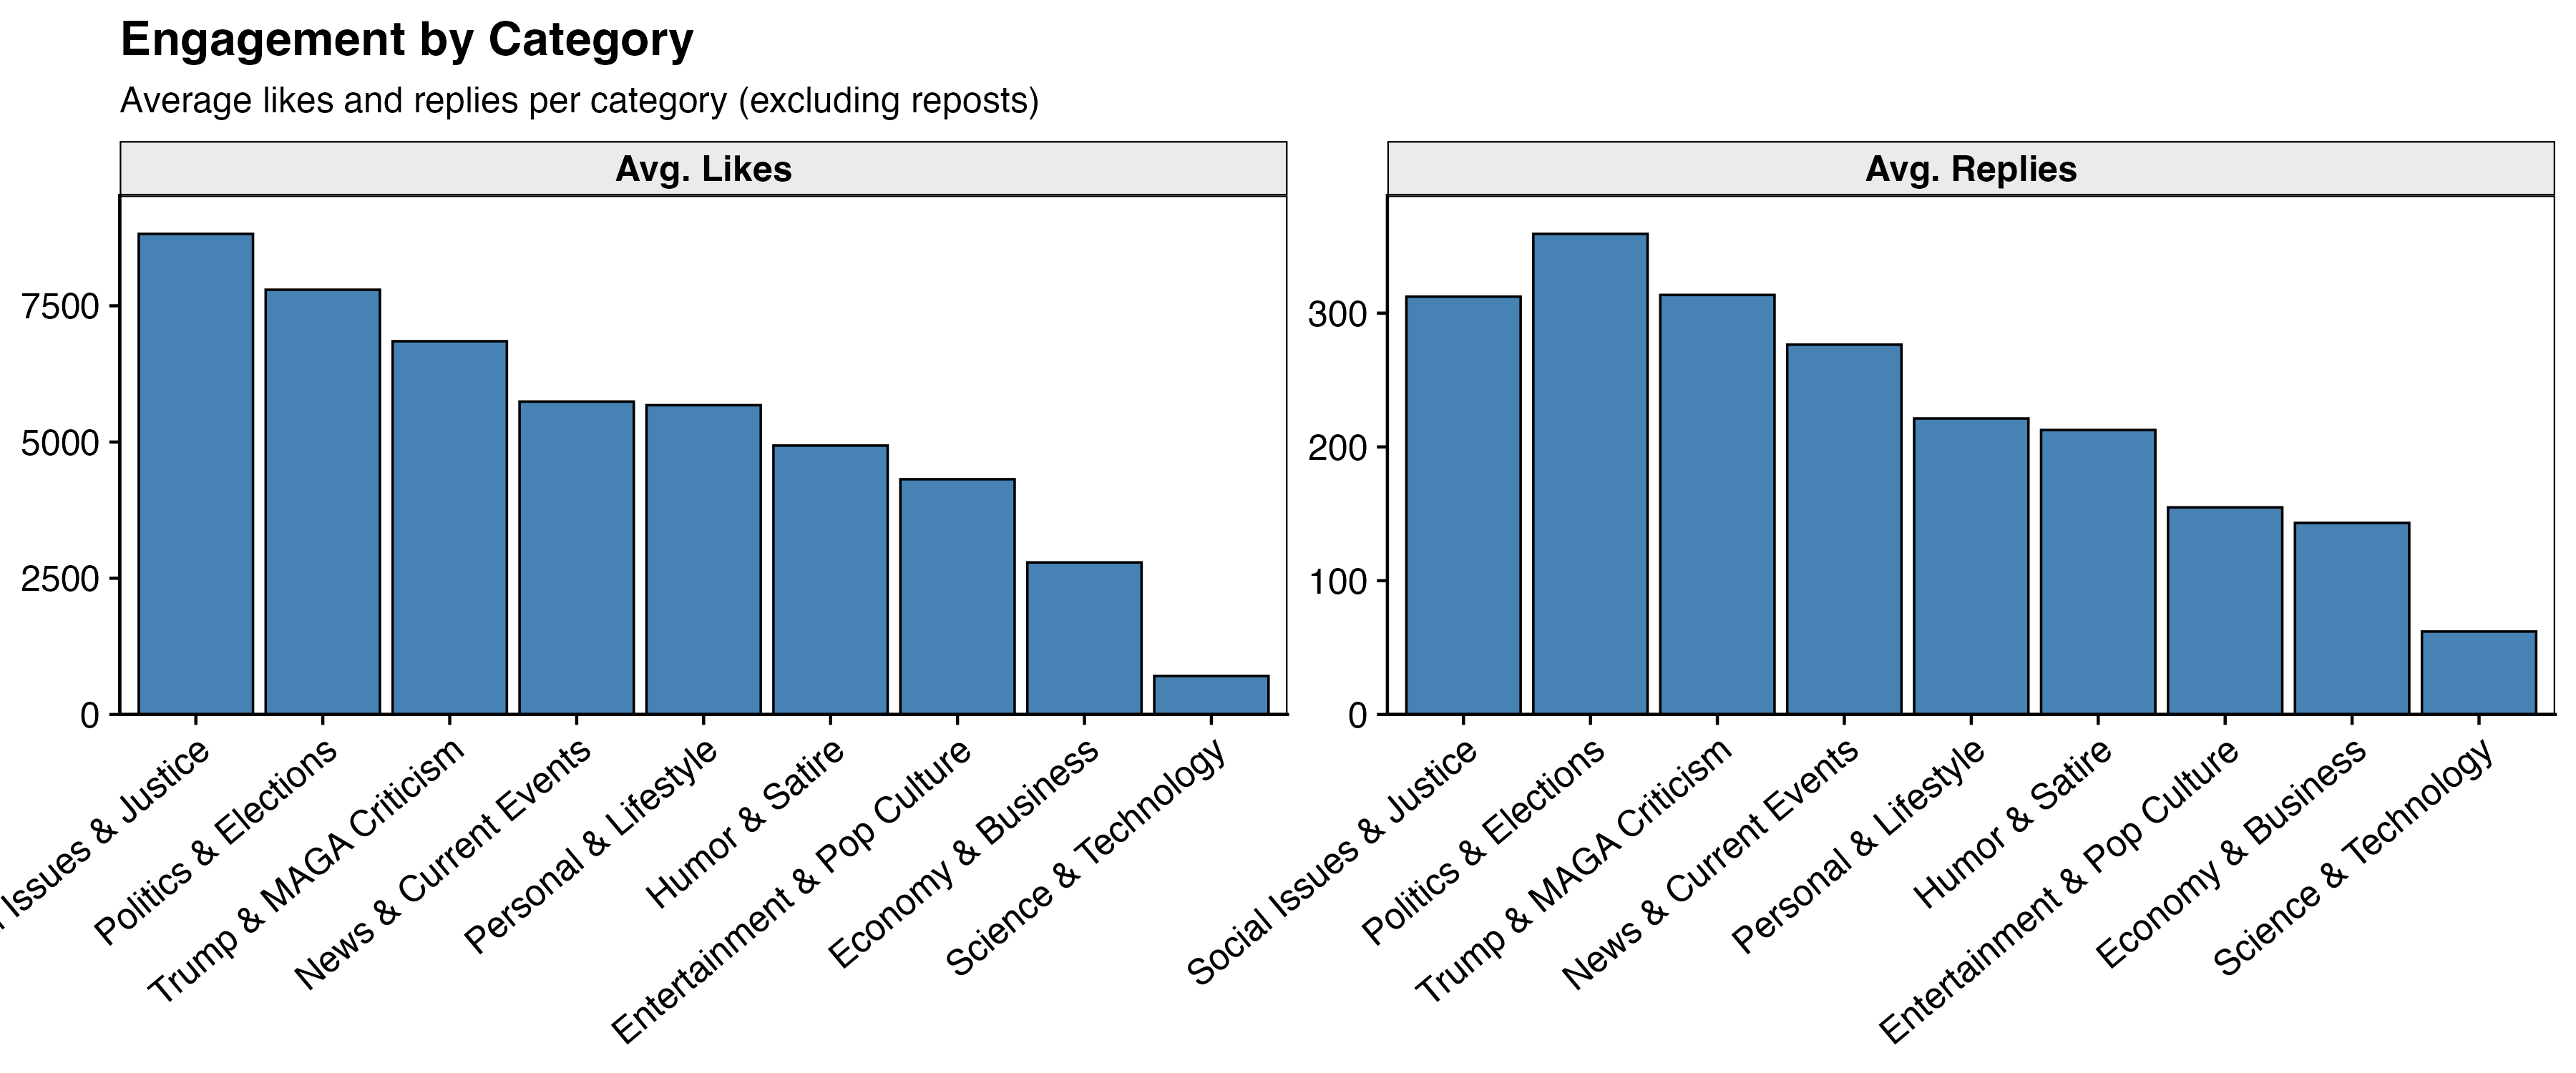
By category, the engagement hierarchy tells a clean story. Social Issues & Justice leads at 8,819 average likes per post, followed by Politics & Elections at 7,795 and Trump & MAGA Criticism at 6,849. Economy & Business posts average just 2,790 likes; Science & Technology posts average only 706 — by far the lowest of any category.
But engagement averages are heavily influenced by who posts in each category. AOC posts almost entirely in Politics and Social Issues; Mark Cuban posts almost entirely in Economy. These raw category averages are partly measuring account popularity, not content appeal in isolation.
What Predicts Likes?
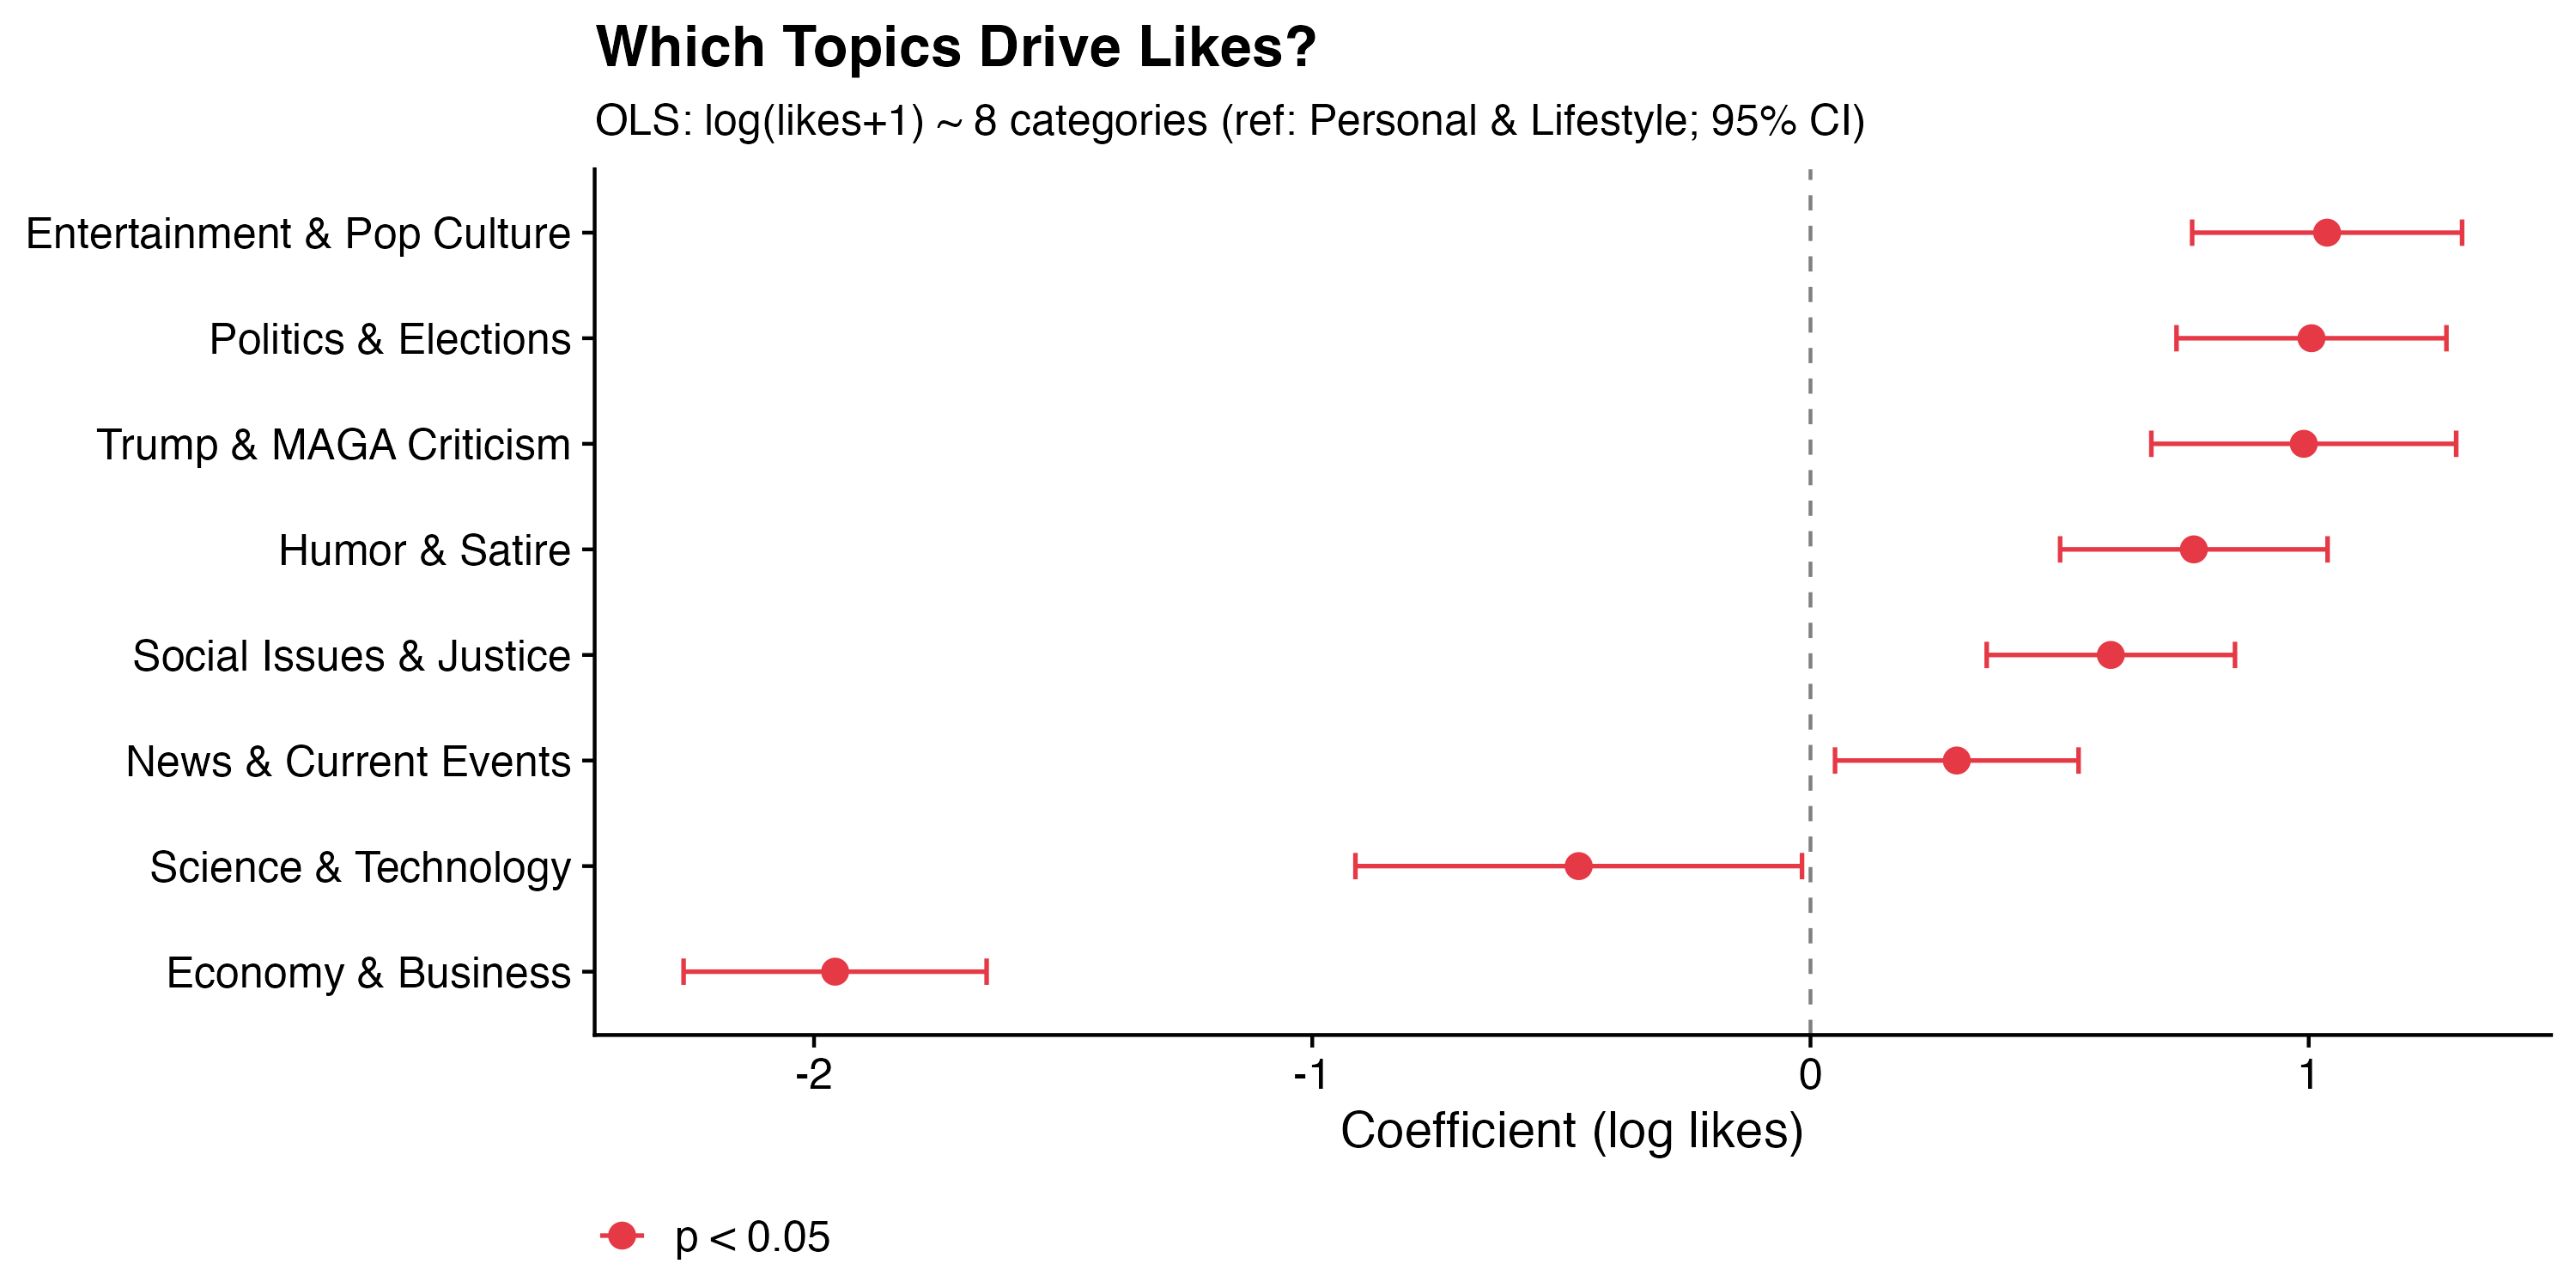
To separate content from creator, I ran two regression models with log(likes + 1) as the outcome — a log transformation that handles the extreme right skew in likes (the median is 919, the max is 167,305).
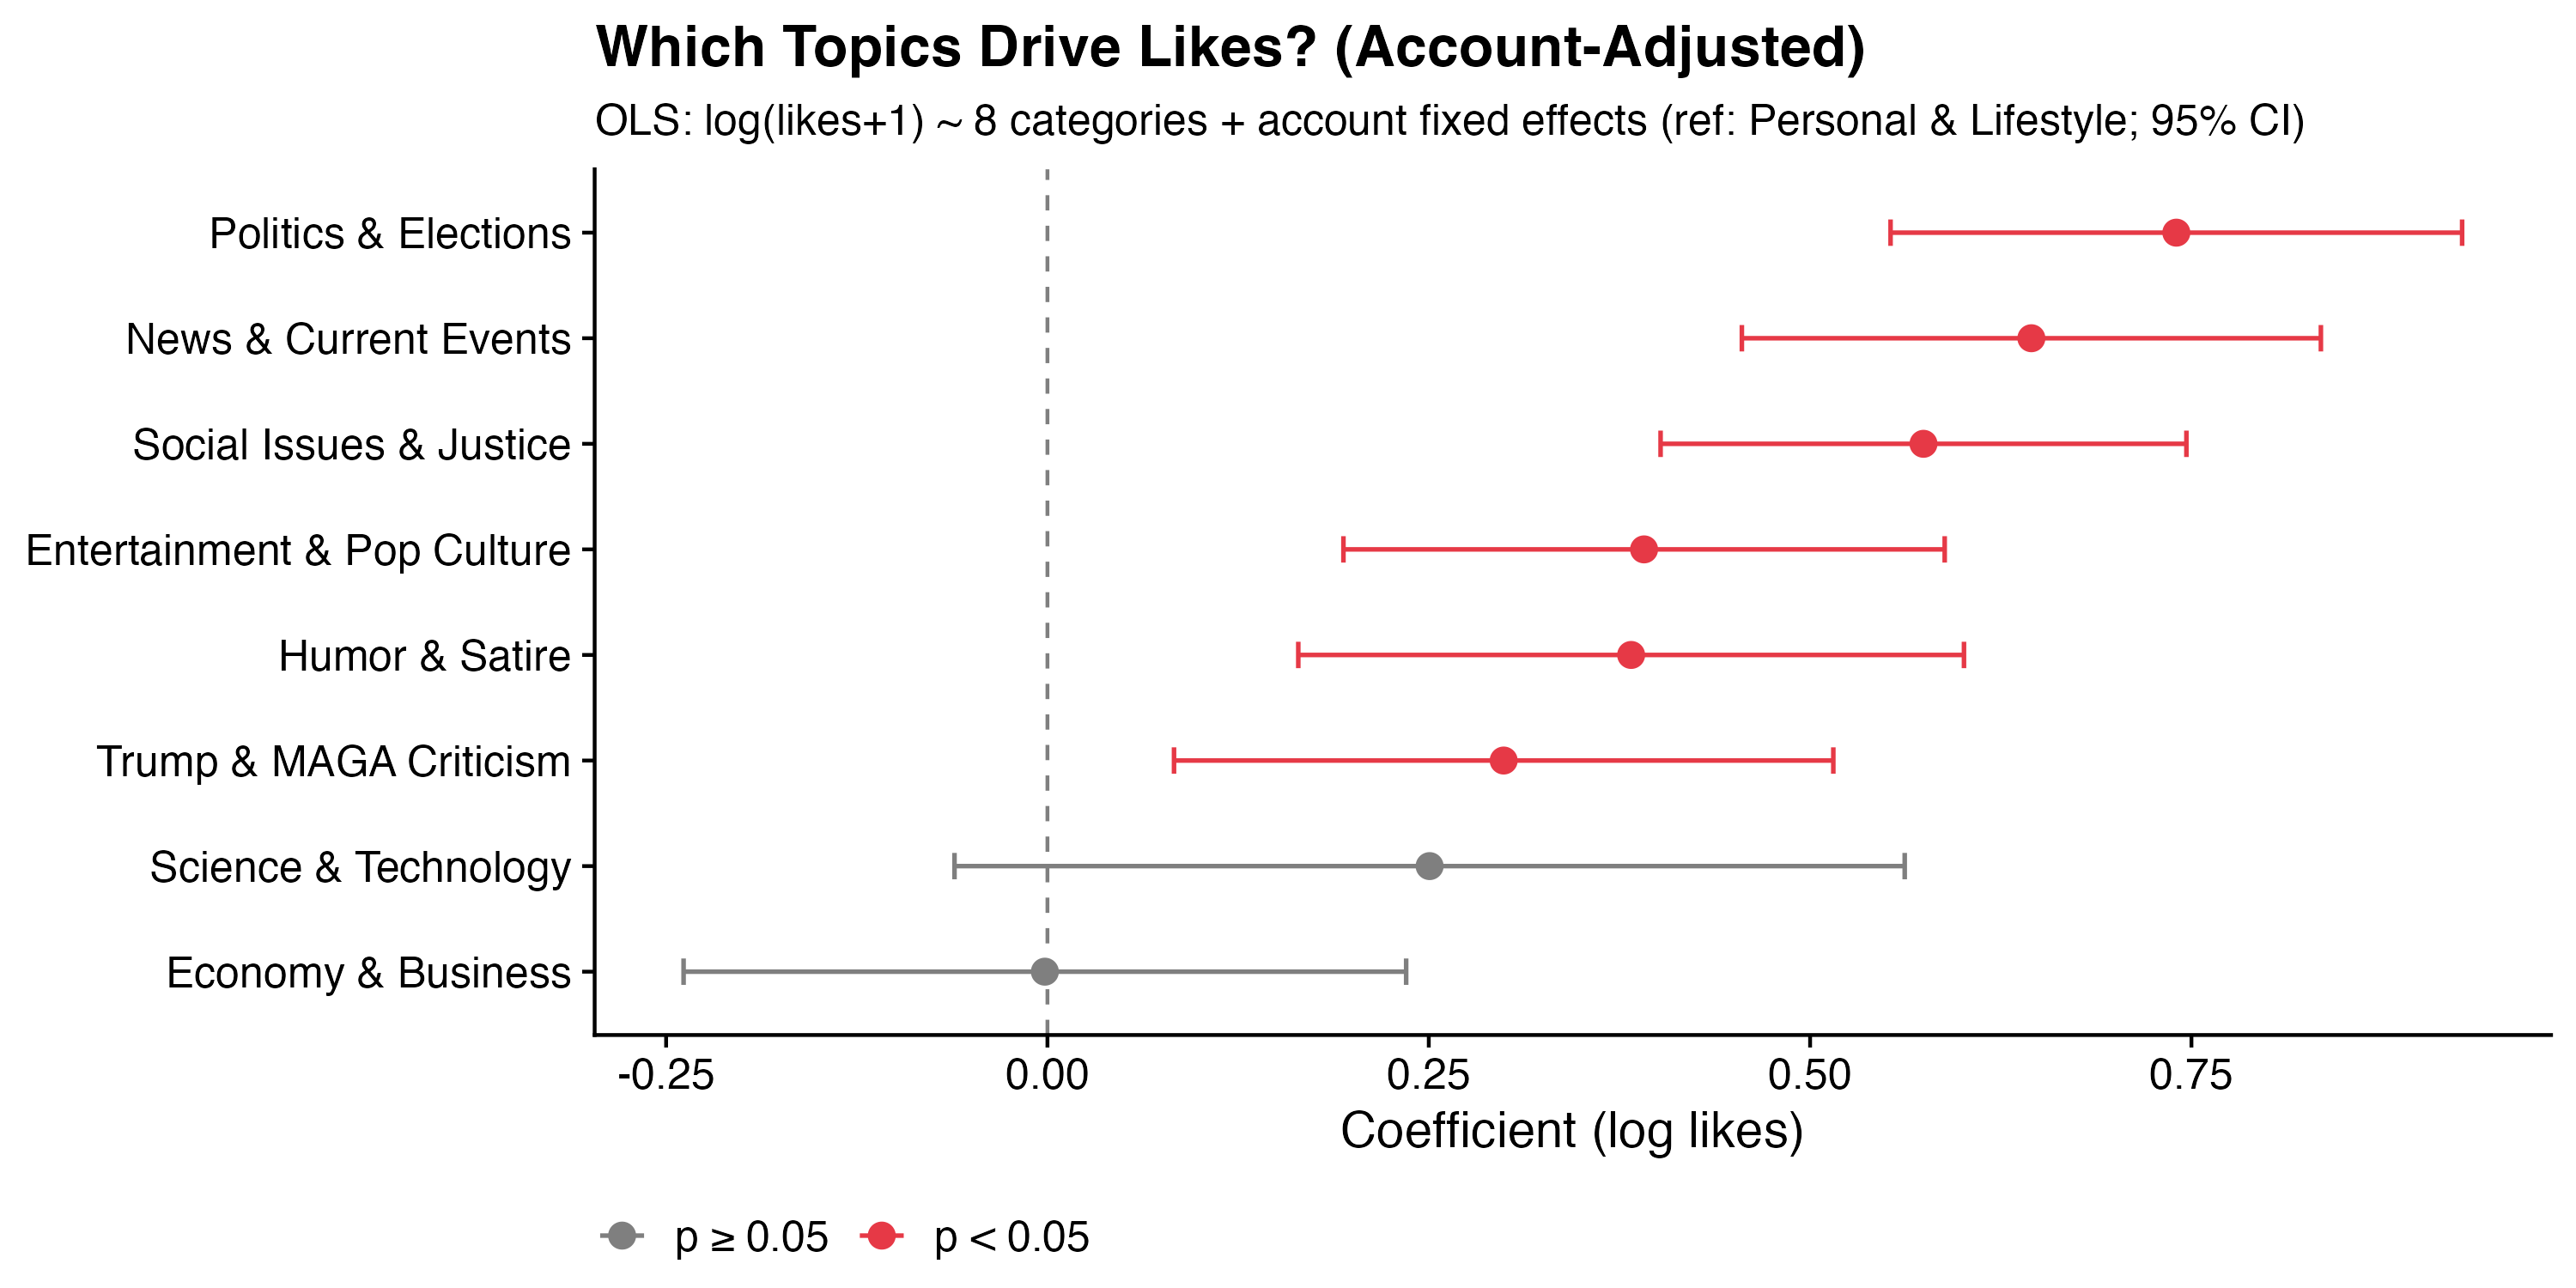
The first model includes only the eight category indicators, with Personal & Lifestyle as the omitted reference category. The second adds account fixed effects, which isolates the content effect from the very large differences in per-account audience.
Before controlling for account, seven of eight categories are statistically significant predictors of likes relative to Personal & Lifestyle posts. The strongest positive predictors:
Entertainment & Pop Culture: +1.04 log-units (the largest positive coefficient)
Politics & Elections: +1.01
Trump & MAGA Criticism: +0.99
Humor & Satire: +0.77
Social Issues & Justice: +0.60
News & Current Events: +0.29
The two negative predictors are striking: Science & Technology (−0.47) and especially Economy & Business (−1.96) — the single largest coefficient in the model, and hugely negative. An economics post generates dramatically fewer likes than a comparable personal post in this raw model. The model explains 18.1% of the variance in log-likes.
But much of this is just reflecting AOC’s enormous engagement. AOC rarely posts about the Economy; Cuban almost exclusively does, and Cuban averages 139 likes per post. Once we account for who’s posting, the picture shifts considerably.
With account fixed effects added, R² jumps from 18.1% to 61.9% — the vast majority of the variance in likes is explained by who posted, not what they posted about. But the content effects don’t disappear; they just reorganize.
Politics & Elections (0.74), News & Current Events (0.65), Social Issues & Justice (0.57), Entertainment & Pop Culture (0.39), Humor & Satire (0.38), and Trump & MAGA Criticism (0.30) all remain positive and significant even after controlling for account. Within any given account, these content types generate more likes than a baseline personal post.
Most striking: Economy & Business goes from −1.96 to −0.002 (effectively zero, p = 0.99). The raw negative effect was entirely due to compositional differences between accounts — Cuban is the economy poster, and Cuban gets very few likes. Once you control for the account posting it, economics content performs no differently than personal content. The category itself isn’t the problem; the platform just happens to have its economics-focused account underperform on likes.
Science & Technology also loses its negative coefficient entirely once account is controlled (it becomes +0.25, non-significant). Science content doesn’t hurt engagement; it just happens to be posted by accounts that underperform on likes overall.
Does Timing Matter?
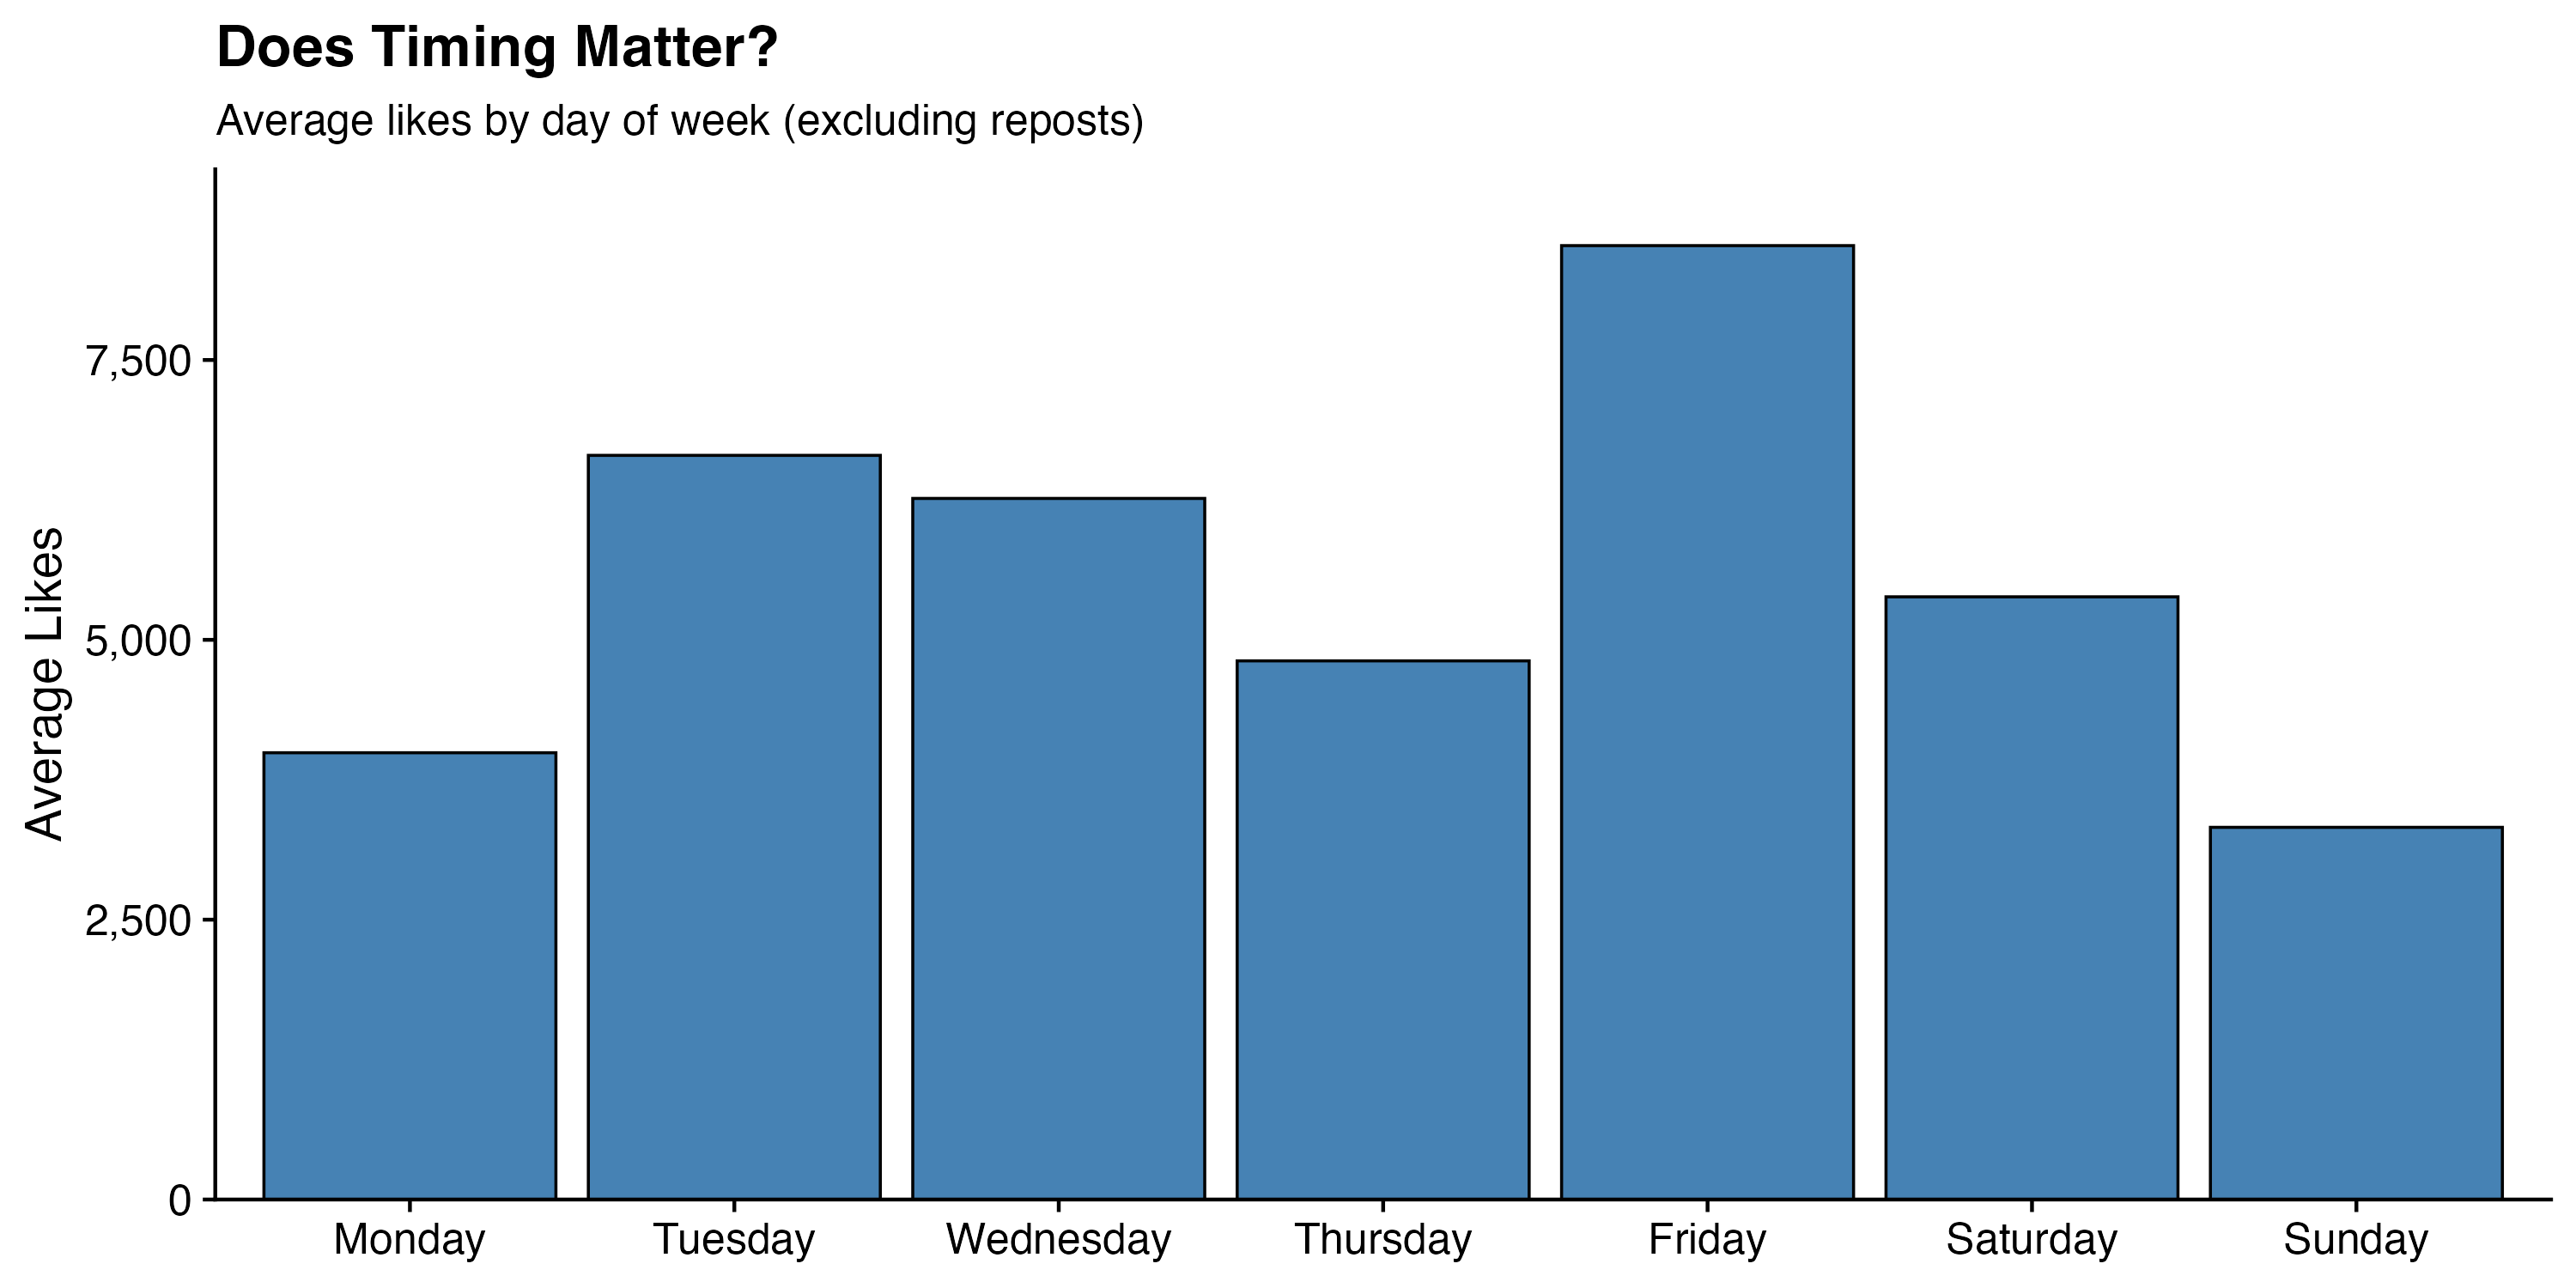
The weekly pattern is clear. Friday is the best day to post at 8,522 average likes, followed by Tuesday (6,648), Wednesday (6,263), and Saturday (5,384). Sunday is the worst day at 3,325 average likes — about 60% lower than Friday’s average.
The spread across days is meaningful but not enormous compared to the account-level differences. Moving from Sunday to Friday would roughly double your average likes in this dataset. Moving from NPR to AOC would multiply them by about 380.
The scatter plot shows every original post (log scale) colored by account. The AOC cluster sits visibly higher and to the right than every other account — more likes and more replies. The media organizations (NYT, NPR) cluster near the bottom. Most posts across all accounts sit in the low-engagement zone regardless of content type; the viral outliers are rare and concentrated in a small number of accounts.
The Public Dataset
The full classified dataset — 2,500 posts, 10 accounts, 9 binary category columns, engagement metrics — is available at chrissoria/bluesky-top10-classified on Hugging Face.
Each row is a post with columns for: account_name, account_handle, timestamp, social_media_input (the post text), likes, replies, reposts, is_repost, category_1 through category_9, and several derived fields including post_length, contains_url, and contains_image. All classification was done by GPT-4o-mini in a single-pass, no-ensemble run. For research applications requiring higher accuracy, a multi-model ensemble is straightforward to add.
A few things you could do with this dataset that I haven’t:
Sentiment analysis by account — which accounts skew optimistic vs. cynical?
Topic evolution over time — has the distribution shifted as the news cycle changed?
Reply rate vs. like rate — some content generates conversation without generating likes; which category does that?
Cross-platform comparison — the same 10 accounts presumably post on other platforms; how does Bluesky compare to X or Instagram in terms of what they share?
How to Run It Yourself
cat-vader handles the data pull and classification in a single call. Here’s the full workflow for replicating this analysis on any Bluesky account:
importcatvaderascvresults=cv.classify(sm_source="bluesky",handle="aoc.bsky.social",# any Bluesky handle
sm_posts=250,# number of recent posts to fetch
categories=["Politics & Elections","Trump & MAGA Criticism","Social Issues & Justice","News & Current Events","Entertainment & Pop Culture","Humor & Satire","Science & Technology","Economy & Business","Personal & Lifestyle",],description="Social media posts from a public Bluesky account",api_key="your-openai-api-key",user_model="gpt-4o-mini",)results.to_csv("bluesky_classified.csv",index=False)
The output is a DataFrame with one row per post and binary columns for each category. From there, any standard analysis pipeline applies — R, Python, whatever you prefer.
One difference from the Threads workflow: Bluesky doesn’t require OAuth or a developer account. The public API is unauthenticated for reading public posts. You just need an OpenAI (or other provider) key for the classification step.
The consistent finding across both the Threads analysis and this one is that who is posting matters far more than what they post. Account identity — follower count, posting frequency, platform reputation — explains more of the variance in engagement than any content category. But content is not irrelevant: within any given account, political and social posts consistently outperform baseline personal posts, and that effect survives account controls.
For Bluesky specifically, the platform’s current character as a haven for politically engaged progressives shows up plainly in the data. Even The Onion — a satirical outlet that theoretically covers everything — lands 81% of its posts in Humor & Satire while still earning engagement that tracks the political intensity of the moment. The platform has a distinct topical gravity, and the accounts doing best are the ones whose content aligns with it.
If you build something interesting with the dataset or the cat-vader pipeline, reach out at chrissoria@berkeley.edu.